

CoreWeave has deployed a multi-rack NVIDIA Vera Rubin NVL72 cluster on CoreWeave Cloud, connecting hundreds of Rubin GPUs into a single scale-out environment aimed at agentic AI workloads. Each Dell-built rack carries 72 Rubin GPUs, 36 Vera CPUs, NVLink 6 as the scale-up fabric, DPU BlueField-4, and two ConnectX-9 SuperNICs per GPU, and the racks connect over NVIDIA Spectrum-X Ethernet in a two-tier, non-blocking fabric that CoreWeave says scales to roughly 128,000 GPUs. CoreWeave is the first cloud provider to validate and bring up a single Vera Rubin NVL72 and the first to publish measured performance from one; the platform’s first peer-reviewed numbers arrived in Inférence MLPerf v6.1 last week, where CoreWeave’s own submission ran on GB300 NVL72. Alongside the compute, CoreWeave AI Object Storage picks up cross-region write acceleration and a new Archive tier.
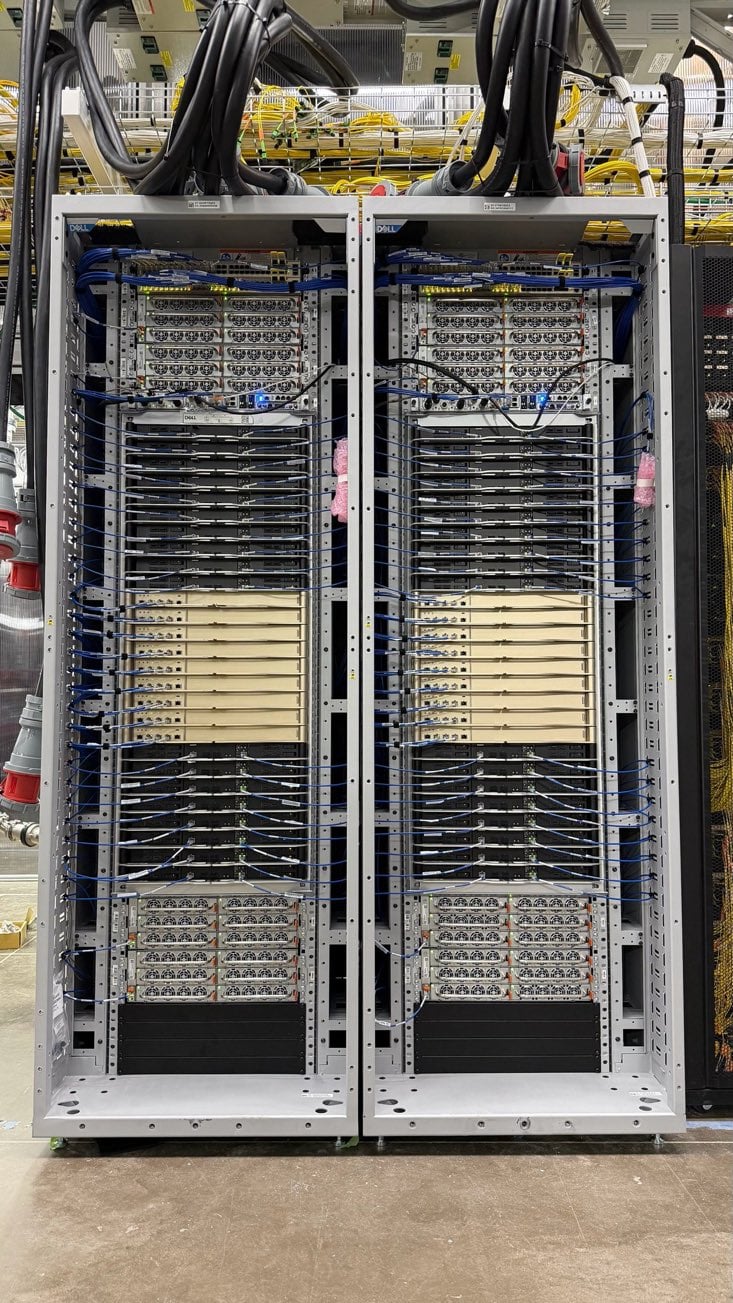
Multi-Rack NVIDIA Vera Rubin NVL72 Architecture
The multi-rack build targets agentic execution paths, where serial reasoning loops and external tool calls compound data-access latency across distributed infrastructure. The two ConnectX-9 SuperNICs on each Rubin GPU provide up to 1.6 Tb/s of backend network connectivity per GPU across multi-rail, multi-plane paths, and CoreWeave describes the fabric as modular, so additional NVL72 racks join the same non-blocking topology as capacity grows. The racks run on 45°C liquid cooling.
CoreWeave ties the racks together through its Mission Control software. A Rack LifeCycle Controller handles provisioning and lifecycle for each rack, hardware detection through firmware flashing, validation, power, and thermal loops; a rack-management layer called Racky controls power and infrastructure; and a programmable cooling controller called Valvey gives software-defined visibility and control over the liquid-cooling loops and environmental sensors.
Racks reach production only after a staged validation pass. At the node level, that means hours of repeated GPU diagnostics, CPU-to-GPU transfer checks, interconnect and thermal validation under load, and realistic training runs. At the rack level, synchronized jobs across all 72 GPUs verify NVLink GPU-to-GPU performance, and any system landing below the expected range goes to troubleshooting. Across racks, CoreWeave runs distributed workloads, deliberately disables the NVLink paths to force traffic over the backend network, and watches the physical fabric for flaky links, rising error rates, overheating hardware, and uneven traffic, with load patterns that mimic agentic applications: sudden demand spikes, shifting concurrency, and bursts of communication. CoreWeave’s write-up on the multi-rack bring-up walks through each stage and makes an interesting read.
AI Object Storage Updates: Cross-Region Writes and Archive Tier
The storage side builds on Stockage d'objets IA CoreWeave and its Local Object Transport Accelerator (LOTA), a caching proxy that runs on every GPU and CPU node in CoreWeave Kubernetes Service and holds objects on node-local NVMe. CoreWeave reports cached reads at up to 7 GB/s per GPU with p99 read latency more than 8x lower than reading from the bucket, and cites one frontier model provider running LOTA across more than 15,000 GPUs and 20PB of cache at a 99.7 percent hit rate. LOTA carries no additional charge.
Cross-region write acceleration lets an application write to a bucket in a remote region at local latency without API or SDK changes. The application issues a standard S3 write to the LOTA endpoint; the object data lands durably in the local region while the metadata commits to the remote one; the object is immediately readable, including by the job that wrote it; and the data migrates to the remote region in the background. Applications see a single bucket namespace across regions with uniform IAM policies, lifecycle rules, and access controls, which removes the per-region forks and replication pipelines that checkpoint distribution across sites usually requires.
“Our datasets span multiple regions, and we can’t afford to have our training schedule dictated by cross-region retrieval delays,” said Cécile Robert-Michon, director of internal infrastructure at Cohere. “CoreWeave AI Object Storage gives us a unified dataset footprint across regions with reads cached locally, so nothing waits on the network.”
The Archive tier is a fourth storage class alongside Hot, Warm, and Cold, built for data that is written once and read rarely, such as older training checkpoints and raw datasets. It carries lower base-capacity pricing and drops retrieval, cache, per-request, early-deletion, tiering, and egress fees. CoreWeave’s suggested pattern keeps recent checkpoints in the faster tiers for immediate restarts and auto-tiers them to Archive after 60 days without a read. Both cross-region writes and the Archive tier are available now; CoreWeave’s storage post has the configuration details.


 Amazon