

WhiteFiber has made WhiteFiber Continuum commercially available, turning the two-site GPU supercluster it first detailed as 레드우드 프로젝트 in July into a product enterprises can deploy. WhiteFiber calls Continuum its highest-performance cross-data-center networking solution and the first commercially available distributed GPU supercluster architecture. It links geographically separated data centers into a single logical GPU supercluster, and WhiteFiber says that removes bandwidth and throughput as constraints on how and where AI infrastructure can be deployed.
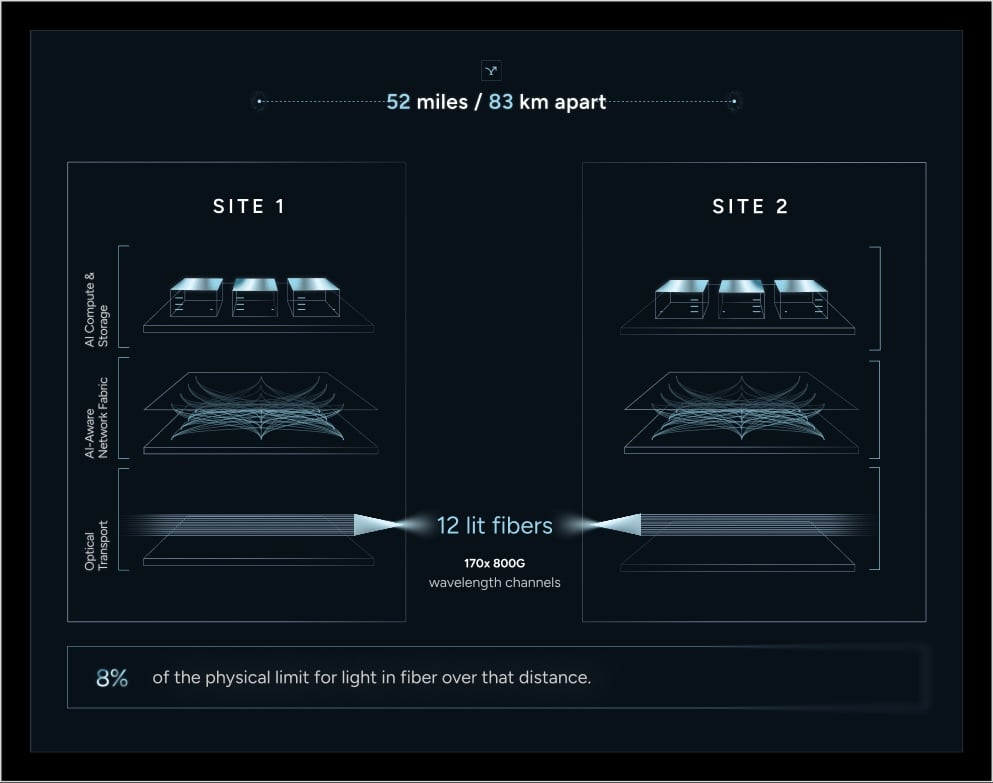
Continuum runs across two HITRUST-certified QTS facilities 83 kilometers apart, joined over 12 Zayo dark fiber strands, with DriveNets AI Fabric carrying the network and WEKA NeuralMesh providing data storage and memory infrastructure across the cluster. WhiteFiber rates the architecture at 136 Tbps of aggregate bandwidth, which its product page breaks out as 170 800G wavelength channels, with 0.9 milliseconds of guaranteed round-trip latency that it says is within 8% of the physical limit for light in fiber over that distance. The July R&D result measured 111.2 Tbps on part of the fiber spectrum; WhiteFiber says the design reaches 136 Tbps after additional wavelengths come online, and full-fiber spectrum testing is underway to confirm the guaranteed commercial specifications. The company has submitted patent applications for the underlying implementation.
“WhiteFiber Continuum is the infrastructure answer to a problem the industry has lived with for years: geographic distance as a ceiling on what a cluster can do,” said Sam Tabar, CEO of WhiteFiber. “Today we are making it commercially available to enterprises that need AI compute to perform at scale, hold up under compliance requirements, and not break when a single site has a problem.”
DriveNets AI Fabric Across the 83 km Link
DriveNets supplies the Ethernet-based AI Fabric connecting both sites, the same role it played in the July R&D work. “DriveNets’ Ethernet-based AI fabric delivers the highest performance even in the most demanding, high-bandwidth, low-latency environments, ensuring scale-across superclusters move data efficiently, maximize GPU utilization, and optimize power efficiency,” said Yossi Kikozashvili, VP Product and GTM for AI Infra at DriveNets. WhiteFiber’s product page says both sites carry live traffic at the same time and only model gradients cross the inter-site link, so a single job can run across the full cluster or split into independent workloads that burst across sites as demand shifts.
WEKA NeuralMesh as the Shared Data Layer
WEKA provides the storage and memory tier with 뉴럴메쉬, which gives Continuum a single storage and memory foundation spanning both facilities. Liran Zvibel, co-founder and CEO at WEKA, said “a supercluster is only as unified as its data,” adding that “WEKA’s NeuralMesh gives Continuum a single, high-performance storage and memory foundation across sites, so GPUs that sit many kilometers apart operate as if the data were local.”
Power Aggregation and Regulatory Data Boundary Control
Continuum lets telecom and metro facilities with spare power and fiber capacity contribute to a single logical GPU supercluster, which WhiteFiber pitches as a way to turn stranded telco and metro assets into capacity for last-mile inference and agent workloads. Enterprises can use the same architecture to pool GPUs across sites and get past the power and space ceiling of a single campus, adding overflow training and inference capacity without standing up a separate greenfield deployment. For regulated industries, WhiteFiber says Continuum keeps sensitive workloads within their originating jurisdiction while failover and pooled compute happen across locations, and because neither site is a single point of failure, it’s designed so training runs continue when one location goes down.
WhiteFiber says additional sites can join the same logical cluster over time using the same networking approach, and it’s hosting a technical walkthrough of the architecture with DriveNets and WEKA on October 14.


 아마존