

Hot Chips 2026 မှာ Intel ဟာ data center၊ inference နဲ့ edge tiers တွေအထိ ကျယ်ပြန့်တဲ့ enterprise agentic AI workloads တွေကို ပစ်မှတ်ထားတဲ့ လာမယ့် silicon platform သုံးခုအတွက် architectural details တွေကို တင်ပြခဲ့ပါတယ် ။ production မှာ workload orchestration အတွက် Diamond Rapids လို့ ကုဒ်နံမည်ပေးထားတဲ့ next-generation Xeon processor၊ high-density inference အတွက် ရည်စူးထားတဲ့ Crescent Island data center GPU နဲ့ client နဲ့ edge devices တွေအတွက် Intel Core Series 3 အဖြစ် တံဆိပ်ကပ်ထားတဲ့ Wildcat Lake SoC တို့ ပါဝင်ပါတယ်။
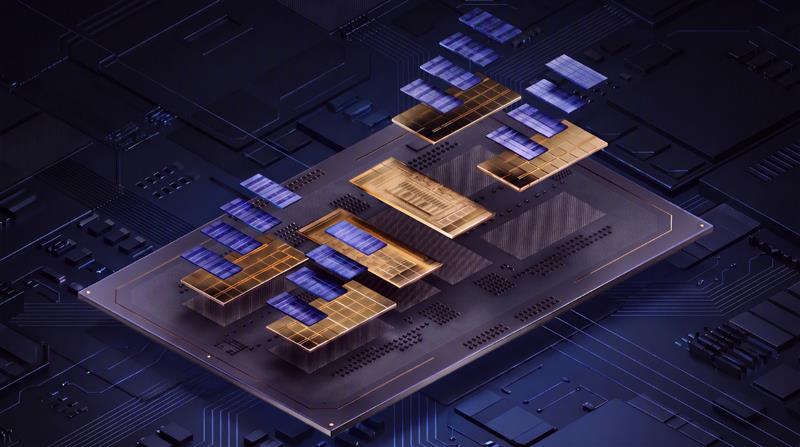
Intel နည်းပညာပိုင်းဆိုင်ရာ ဦးဆောင်မှုအရ၊ အေးဂျင့် AI workloads များသည် အထွေထွေရည်ရွယ်ချက် compute ကို dedicated acceleration၊ အဆင့်မြင့် packaging နှင့် modular chiplet interconnects တို့နှင့် တွဲဖက်ထားသည့် ကွဲပြားသော ဒီဇိုင်းများ လိုအပ်သည်။ Intel Foundry 18A process node မိသားစုတွင် တည်ဆောက်ထားသော၊ platform သုံးခုကို enterprise deployments တစ်လျှောက်ရှိ power၊ bandwidth နှင့် density လိုအပ်ချက်များကို ဖြည့်ဆည်းရန် Foveros Direct 3D packaging နှင့် Universal Chiplet Interconnect Express (UCIe) open standard တို့က ကျောထောက်နောက်ခံပြုထားကြောင်း Intel က ပြောကြားခဲ့သည်။
Diamond Rapids: မြင့်မားသော Core-Count Compute နှင့် I/O အခြေခံ
စွမ်းဆောင်ရည်မြှင့်တင်ထားသော Intel 18A-P process node ပေါ်တွင်တည်ဆောက်ထားသော Diamond Rapids သည် Intel ၏ နောက်မျိုးဆက် Xeon ဗိသုကာလက်ရာကို ကိုယ်စားပြုပြီး agentic workflows နှင့် ကြီးမားသော enterprise computing ကို စီစဉ်ရန် ဒီဇိုင်းထုတ်ထားသည်။ system-on-chip သည် modular compute tiles များကို unified memory subsystem နှင့် high-speed I/O ဖြင့် ချိတ်ဆက်ရန် Foveros Direct 3D stacking နှင့် UCIe-S interconnects များကို အသုံးပြုသည်။
- 1.28GB LLC ဖြင့် core အသစ် ၂၅၆ ခုအထိ
- 12,800 MT/s တွင် မှတ်ဉာဏ်ချန်နယ် ၁၆ ခု
- PCIe Gen6 နှင့် CXL 3.0 ၏ လမ်းကြောင်း ၁၂၈ ခု
ဆီလီကွန် လုပ်ဆောင်မှု အရင်းအမြစ်များအရ၊ ပလက်ဖောင်းသည် Last Level Cache (LLC) 1.28 GB ဖြင့် ကျောထောက်နောက်ခံပြုထားသော ရုပ်ပိုင်းဆိုင်ရာ core ၂၅၆ ခုအထိ တိုးချဲ့နိုင်သည်။ Compute မြှင့်တင်မှုများတွင် Intel Advanced Performance Extensions (APX) နှင့် အပ်ဒိတ်လုပ်ထားသော Advanced Matrix Extensions (AMX) ညွှန်ကြားချက်များ ပါဝင်သည်။ မှတ်ဉာဏ်နှင့် ဘတ်စ်ကားချိတ်ဆက်မှုတွင် မျိုးဆက်တစ်ခုပြီးတစ်ခု သိသိသာသာ တိုးလာသည်ကို တွေ့ရသည်- ဗိသုကာပုံစံသည် ဒေတာနှုန်းထားများကို 12,800 MT/s အထိ ပံ့ပိုးပေးသည့် မှတ်ဉာဏ်ချန်နယ် ၁၆ ခုကို ပေါင်းစပ်ထားပြီး PCIe Gen6 ၏ လမ်းကြောင်း ၁၂၈ ခုနှင့် Compute Express Link (CXL) 3.0 တို့နှင့်အတူ high-throughput accelerator attachment နှင့် memory expansion ကို စီမံခန့်ခွဲရန် ပေါင်းစပ်ထားသည်။
Crescent Island: စွမ်းရည်မြင့် လေအေးပေးစက်ဖြင့် ကောက်ချက်ချသည့် အရှိန်မြှင့်စက်
Crescent Island သည် ရည်ရွယ်ချက်ရှိရှိတည်ဆောက်ထားသော PCIe accelerator တစ်ခုဖြစ်ပြီး၊ real-time inference နှင့် long-context agentic model များအတွက် token throughput နှင့် operational economics များကို အကောင်းဆုံးဖြစ်အောင် ဒီဇိုင်းထုတ်ထားသည်။ Xe3P architecture ကို အခြေခံ၍ တည်ဆောက်ထားသော ကတ်တွင် Xe cores ၃၂ ခုနှင့် Intel Matrix Extension (XMX) engines ၂၅၆ ခု ပါဝင်သည်။
- Xe3P ကို အခြေခံထားတဲ့ Xe cores ၃၂ ခုနဲ့ XMX အင်ဂျင် ၂၅၆ ခု
- 480GB LPDDR5X မှတ်ဉာဏ်အထိ
- ၃၅၀ ဝပ် လေအေးပေး PCIe ကတ်
ပါဝါသိပ်သည်းသော High Bandwidth Memory (HBM) ကို အားကိုးမည့်အစား Crescent Island သည် LPDDR5X မှတ်ဉာဏ် 480 GB အထိ ပေါင်းစပ်ထားသည်။ ဤမှတ်ဉာဏ်ဗိသုကာလက်ရာသည် accelerator အား ကြီးမားသော parameter မော်ဒယ်များကို လက်ခံထားရှိနိုင်စေပြီး၊ တိုးချဲ့ထားသော context window များကို ပံ့ပိုးပေးနိုင်ကာ 350-watt thermal envelope အတွင်းတွင် ရှိနေစဉ်တွင် concurrent agent များစွာကို ဝန်ဆောင်မှုပေးနိုင်စေပါသည်။ ရုပ်ပိုင်းဆိုင်ရာဒီဇိုင်းသည် စံ PCIe form factor များနှင့် ကိုက်ညီပြီး liquid-cooling conversions မလိုအပ်ဘဲ ရှိပြီးသား air-cooled data center rack များထဲသို့ တိုက်ရိုက်ပေါင်းစပ်နိုင်စေပါသည်။
Wildcat Lake: Client နှင့် Edge SoC ပေါင်းစပ်မှု
mainstream laptop များ၊ ပေါ့ပါးသော mobile workstation များနှင့် intelligent edge appliances များအတွက် တပ်ဆင်ထားသော Wildcat Lake ဟု ကုဒ်နံပါတ်ပေးထားသော Intel Core Series 3 processor မိသားစုသည် client infrastructure သို့ AI execution ယူဆောင်လာပါသည်။ Intel 18A လုပ်ငန်းစဉ်ပေါ်တွင် တည်ဆောက်ထားသော Wildcat Lake သည် Intel ၏ UCIe packaging ကို mainstream client processor ထဲသို့ ပထမဆုံး ပေါင်းစပ်ထားခြင်းဖြစ်ပြီး modular နှင့် ကုန်ကျစရိတ်သက်သာသော silicon assembly များကို ပြုလုပ်နိုင်စေပါသည်။
- စွမ်းဆောင်ရည် core ၂ ခုနှင့် စွမ်းဆောင်ရည် core ၄ ခု
- LPDDR5X-7467 အထိ ပံ့ပိုးမှု
- WiFi 7 နဲ့ Bluetooth 6.0 တို့ဖြစ်ပါတယ်
compute topology သည် single-thread နှင့် background processing ကို ကိုင်တွယ်ရန်အတွက် performance core နှစ်ခုနှင့် efficiency core လေးခုကို ပေါင်းစပ်ထားသည်။ Graphics နှင့် matrix လုပ်ဆောင်ချက်များကို XMX acceleration ပါရှိသော integrated Xe3 GPU ဖြင့် မောင်းနှင်ပြီး hybrid on-device inferencing အတွက် 17 TOPS အထိ အဆင့်သတ်မှတ်ထားသော dedicated Neural Processing Unit (NPU) ဖြင့် ဖြည့်စွက်ထားသည်။ ဤ platform သည် LPDDR5X-7467 memory အထိ ပံ့ပိုးပေးပြီး Wi-Fi 7 နှင့် Bluetooth 6.0 ချိတ်ဆက်မှုကို natively ပေါင်းစပ်ထားသည်။
ဗိသုကာသုံးခုပေါင်းပြီး ဒေတာစင်တာအခြေခံအဆောက်အအုံနှင့် ဖြန့်ဝေထားသော အနားစွန်း node များတစ်လျှောက်တွင် agent AI ဖြန့်ကျက်မှုများ၏ တွက်ချက်မှု၊ မှတ်ဉာဏ်စွမ်းရည်နှင့် အပူချိန်ကန့်သတ်ချက်များကို ဖြေရှင်းရန် Intel ၏ မဟာဗျူဟာကို ဖော်ပြထားသည်။


 အမေဇုံ