

CoreWeave သည် CoreWeave Cloud တွင် multi-rack NVIDIA Vera Rubin NVL72 cluster တစ်ခုကို ဖြန့်ကျက်ထားပြီး agent AI workloads များအတွက် ရည်ရွယ်သည့် single scale-out environment တစ်ခုသို့ Rubin GPU ရာပေါင်းများစွာကို ချိတ်ဆက်ပေးထားသည်။ Dell တည်ဆောက်ထားသော rack တစ်ခုစီတွင် Rubin GPU ၇၂ ခု၊ Vera CPU ၃၆ ခု၊ scale-up fabric အဖြစ် NVLink ၆၊ BlueField-4 DPU များ နှင့် GPU တစ်ခုလျှင် ConnectX-9 SuperNIC နှစ်ခု ပါဝင်ပြီး rack များသည် NVIDIA Spectrum-X Ethernet မှတစ်ဆင့် ချိတ်ဆက်ထားပြီး CoreWeave က GPU ၁၂၈,၀၀၀ ခန့်အထိ တိုးချဲ့နိုင်သည်ဟု ဆိုသည်။ CoreWeave သည် Vera Rubin NVL72 တစ်ခုတည်းကို အတည်ပြုပြီး ယူဆောင်လာသည့် ပထမဆုံး cloud provider ဖြစ်ပြီး တစ်ခုမှ တိုင်းတာထားသော စွမ်းဆောင်ရည်ကို ပထမဆုံး ထုတ်ဝေသူလည်း ဖြစ်သည်။ platform ၏ ပထမဆုံး peer-reviewed နံပါတ်များသည် ပြီးခဲ့သည့်အပတ်က MLPerf Inference v6.1 တွင် ရောက်ရှိလာခဲ့ပြီး CoreWeave ၏ကိုယ်ပိုင် submission သည် GB300 NVL72 တွင် run ခဲ့သည်။ compute နှင့်အတူ CoreWeave AI Object Storage သည် cross-region write acceleration နှင့် Archive tier အသစ်ကို ရယူသည်။
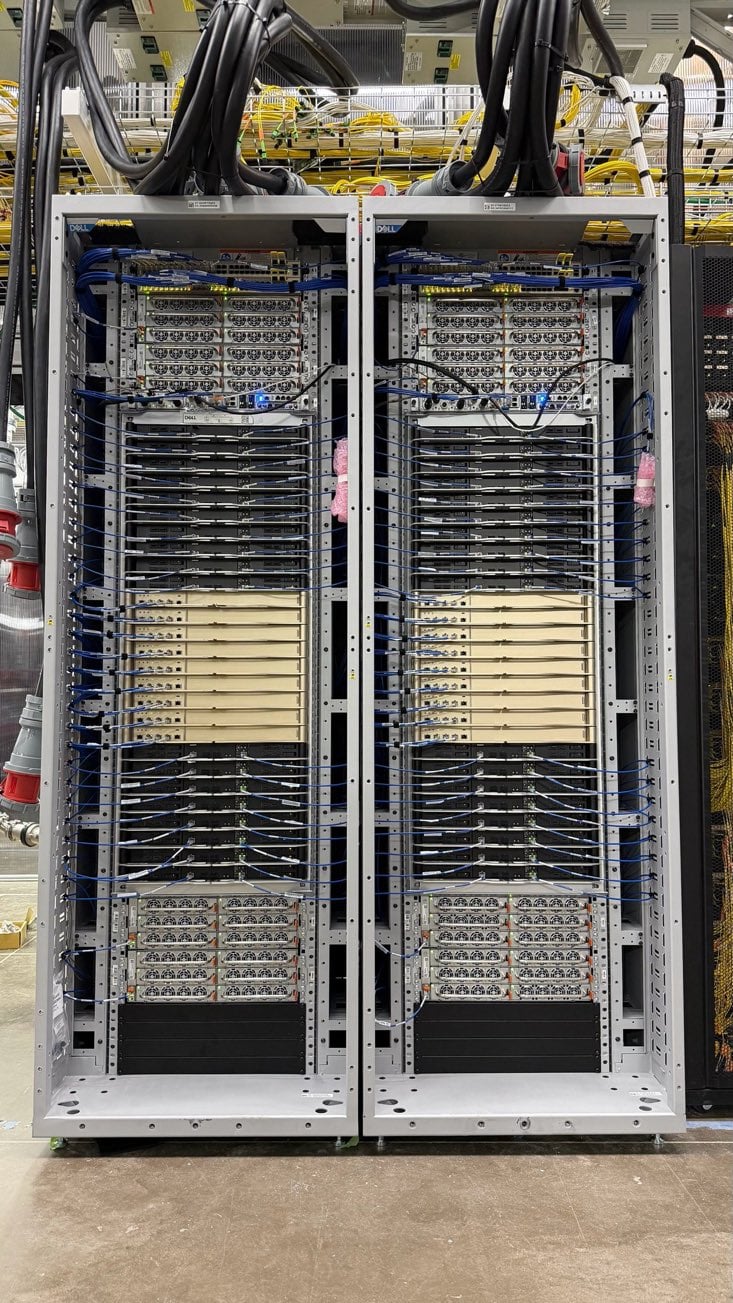
Multi-Rack NVIDIA Vera Rubin NVL72 ဗိသုကာ
multi-rack တည်ဆောက်မှုသည် agentic execution paths များကို ပစ်မှတ်ထားပြီး၊ serial reasoning loops များနှင့် external tool များသည် distributed infrastructure တစ်လျှောက် compound data-access latency များကို ခေါ်ဆိုသည်။ Rubin GPU တစ်ခုစီရှိ ConnectX-9 SuperNICs နှစ်ခုသည် multi-rail၊ multi-plane paths များတစ်လျှောက် GPU တစ်ခုလျှင် backend network ချိတ်ဆက်မှု 1.6 Tb/s အထိ ပေးစွမ်းနိုင်ပြီး CoreWeave သည် fabric ကို modular အဖြစ် ဖော်ပြထားသောကြောင့် စွမ်းရည်တိုးလာသည်နှင့်အမျှ အပို NVL72 racks များသည် တူညီသော non-blocking topology နှင့် ပူးပေါင်းသည်။ racks များသည် 45°C liquid cooling ဖြင့် လည်ပတ်သည်။
CoreWeave သည် ၎င်း၏ Mission Control software မှတစ်ဆင့် rack များကို ချိတ်ဆက်ပေးသည်။ Rack LifeCycle Controller သည် rack တစ်ခုချင်းစီအတွက် provisioning နှင့် lifecycle၊ firmware flashing၊ validation၊ power နှင့် thermal loops များမှတစ်ဆင့် hardware detection တို့ကို ကိုင်တွယ်သည်။ Racky ဟုခေါ်သော rack-management layer သည် power နှင့် infrastructure ကို ထိန်းချုပ်သည်။ Valvey ဟုခေါ်သော programmable cooling controller သည် liquid-cooling loops များနှင့် environmental sensor များအပေါ် software-defined visibility နှင့် control ကို ပေးစွမ်းသည်။
အဆင့်ဆင့် အတည်ပြုချက် အောင်မြင်ပြီးမှသာ Rack များသည် ထုတ်လုပ်မှုသို့ ရောက်ရှိသည်။ node အဆင့်တွင်၊ ဆိုလိုသည်မှာ GPU ရောဂါရှာဖွေခြင်း နာရီပေါင်းများစွာ၊ CPU-to-GPU လွှဲပြောင်းမှု စစ်ဆေးခြင်း၊ load အောက် ချိတ်ဆက်မှုနှင့် thermal validation နှင့် လက်တွေ့လေ့ကျင့်မှု လုပ်ဆောင်ခြင်းတို့ကို ဆိုလိုသည်။ Rack အဆင့်တွင်၊ GPU ၇၂ ခုလုံးတွင် synchronized jobs များသည် NVLink GPU-to-GPU စွမ်းဆောင်ရည်ကို အတည်ပြုပြီး မျှော်မှန်းထားသည့် အကွာအဝေးထက် နိမ့်ကျသော system များသည် troubleshooting သို့ ရောက်ရှိသည်။ Rack များတစ်လျှောက်တွင် CoreWeave သည် distributed workloads များကို လုပ်ဆောင်ပြီး backend network မှတစ်ဆင့် traffic ကို တွန်းအားပေးရန် NVLink paths များကို ရည်ရွယ်ချက်ရှိရှိ disable လုပ်သည်၊ ထို့အပြင် physical fabric တွင် flaky links များ၊ error rates များ မြင့်တက်လာခြင်း၊ hardware အပူလွန်ကဲခြင်းနှင့် traffic မညီမျှခြင်းများကို စောင့်ကြည့်သည်၊ agentic applications များကို အတုယူသည့် load patterns များ- ရုတ်တရက် demand မြင့်တက်လာခြင်း၊ concurrency ပြောင်းလဲခြင်းနှင့် communication များ ပြတ်တောက်ခြင်းတို့ ပါဝင်သည်။ multi-rack bring-up အကြောင်း CoreWeave ၏ ရေးသားချက်သည် အဆင့်တစ်ခုစီကို လမ်းညွှန်ပေးပြီး စိတ်ဝင်စားဖွယ်ကောင်းသော ဖတ်ရှုမှုတစ်ခု ဖြစ်စေသည်။
AI Object Storage အပ်ဒိတ်များ- Cross-Region Writes နှင့် Archive Tier
storage ဘက်ခြမ်းသည် CoreWeave AI Object Storage နှင့် ၎င်း၏ Local Object Transport Accelerator (LOTA) ပေါ်တွင် တည်ဆောက်ထားပြီး CoreWeave Kubernetes Service ရှိ GPU နှင့် CPU node တိုင်းတွင် လုပ်ဆောင်ပြီး node-local NVMe တွင် object များကို သိမ်းဆည်းထားသော caching proxy တစ်ခုဖြစ်သည်။ CoreWeave သည် cached read များကို GPU တစ်ခုလျှင် 7 GB/s အထိ ရရှိနိုင်ပြီး p99 read latency သည် bucket မှ reading ထက် 8 ဆကျော် လျော့နည်းကြောင်း အစီရင်ခံပြီး GPU 15,000 ကျော်နှင့် 20PB cache တွင် LOTA ကို 99.7 ရာခိုင်နှုန်း hit rate ဖြင့် လုပ်ဆောင်နေသော frontier model provider တစ်ခုကို ကိုးကားဖော်ပြထားသည်။ LOTA တွင် အပိုအခကြေးငွေ မရှိပါ။
cross-region write acceleration သည် application တစ်ခုအား remote region ရှိ bucket တစ်ခုသို့ API သို့မဟုတ် SDK ပြောင်းလဲမှုများမရှိဘဲ local latency တွင် ရေးသားနိုင်စေပါသည်။ application သည် LOTA endpoint သို့ standard S3 write ကိုထုတ်ပေးသည်။ metadata သည် remote region သို့ commit လုပ်နေစဉ် object data သည် local region တွင် ကြာရှည်စွာရောက်ရှိသည်။ object ကိုရေးသားသော job အပါအဝင် ချက်ချင်းဖတ်ရှုနိုင်သည်။ data သည် background ရှိ remote region သို့ migrate လုပ်သည်။ Application များသည် uniform IAM policies၊ lifecycle rules နှင့် access controls များပါရှိသော regions များတစ်လျှောက် single bucket namespace ကိုမြင်တွေ့ရပြီး sites များတစ်လျှောက် checkpoint distribution တွင်ပုံမှန်လိုအပ်သည့် per-region forks နှင့် replication pipelines များကိုဖယ်ရှားပေးသည်။
“ကျွန်မတို့ရဲ့ dataset တွေက ဒေသအများအပြားကို လွှမ်းခြုံထားပြီး ဒေသဖြတ်ကျော် ပြန်လည်ရယူမှု နှောင့်နှေးမှုတွေကြောင့် ကျွန်မတို့ရဲ့ လေ့ကျင့်ရေးအချိန်ဇယားကို ကန့်သတ်ထားလို့ မရပါဘူး” ဟု Cohere ၏ အတွင်းပိုင်း အခြေခံအဆောက်အအုံ ဒါရိုက်တာ Cécile Robert-Michon က ပြောကြားခဲ့သည်။ “CoreWeave AI Object Storage က ဒေသတစ်လျှောက်မှာ read တွေကို cache လုပ်ထားတဲ့ စုစည်းထားတဲ့ dataset footprint ကို ပေးစွမ်းတာကြောင့် ကွန်ရက်ပေါ်မှာ ဘာမှ စောင့်မနေပါဘူး။”
Archive tier သည် Hot၊ Warm နှင့် Cold တို့နှင့်အတူ စတုတ္ထမြောက် storage class တစ်ခုဖြစ်ပြီး တစ်ကြိမ်ရေးပြီး ရှားရှားပါးပါးသာ ဖတ်ရသော data များအတွက် တည်ဆောက်ထားသည်။ ၎င်းတွင် base-capacity ဈေးနှုန်းနိမ့်ပြီး retrieval၊ cache၊ per-request၊ early-deletion၊ tiering နှင့် egress fees များကို လျှော့ချထားသည်။ CoreWeave ၏ အကြံပြုထားသော ပုံစံသည် မကြာသေးမီက checkpoints များကို ချက်ချင်း restart လုပ်ရန်အတွက် ပိုမိုမြန်ဆန်သော tiers များတွင် သိမ်းဆည်းထားပြီး read မလုပ်ဘဲ ရက်ပေါင်း ၆၀ ကြာပြီးနောက် Archive သို့ auto-tiers ပေးပါသည်။ cross-region writes နှင့် Archive tier နှစ်ခုလုံးကို ယခုရရှိနိုင်ပါပြီ။ CoreWeave ၏ storage post တွင် configuration အသေးစိတ်အချက်အလက်များ ပါရှိသည်။


 အမေဇုံ