StorageReview.com
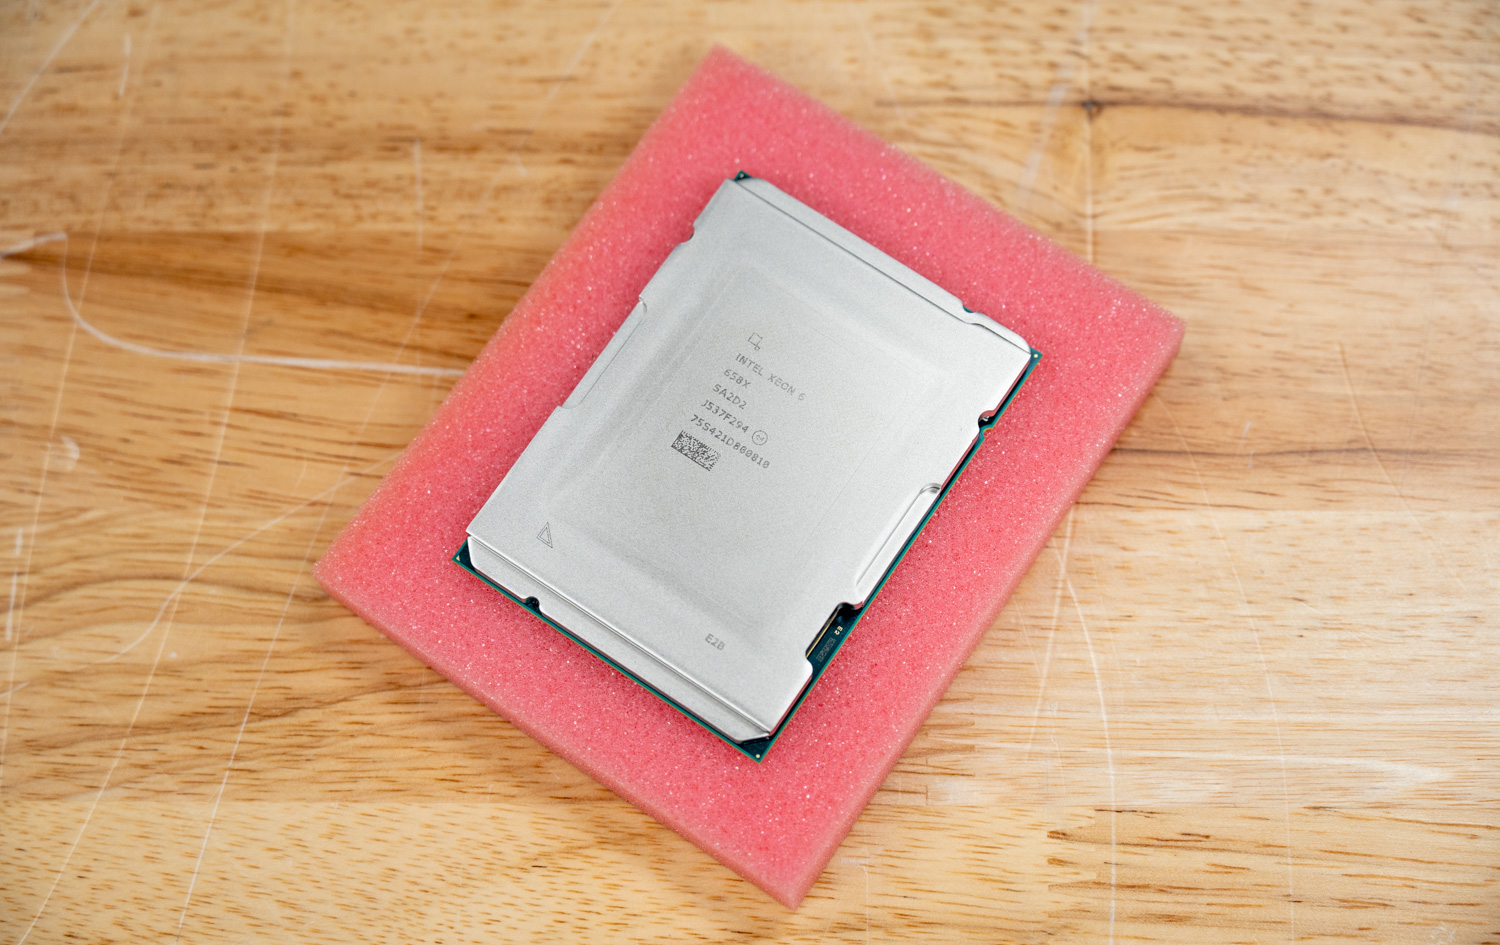
Intel Xeon 6 processor on anti-static foam in the StorageReview lab, one of the two x86 CPU families that oneDNN will cover for PyTorch
Enterprise  ◇  Software

AMD and Intel Make oneDNN the Default x86 Path in PyTorch, Folding ZenDNN In and Lining Up AI Compute Extensions

AMD and Intel announced that they will combine their x86 CPU optimization work for PyTorch in oneDNN, the open-source deep learning library governed by the Unified Acceleration Foundation (UXL), and have aligned on it as the default open-source library for x86 acceleration inside PyTorch. AMD is folding its ZenDNN optimizations into oneDNN and has joined
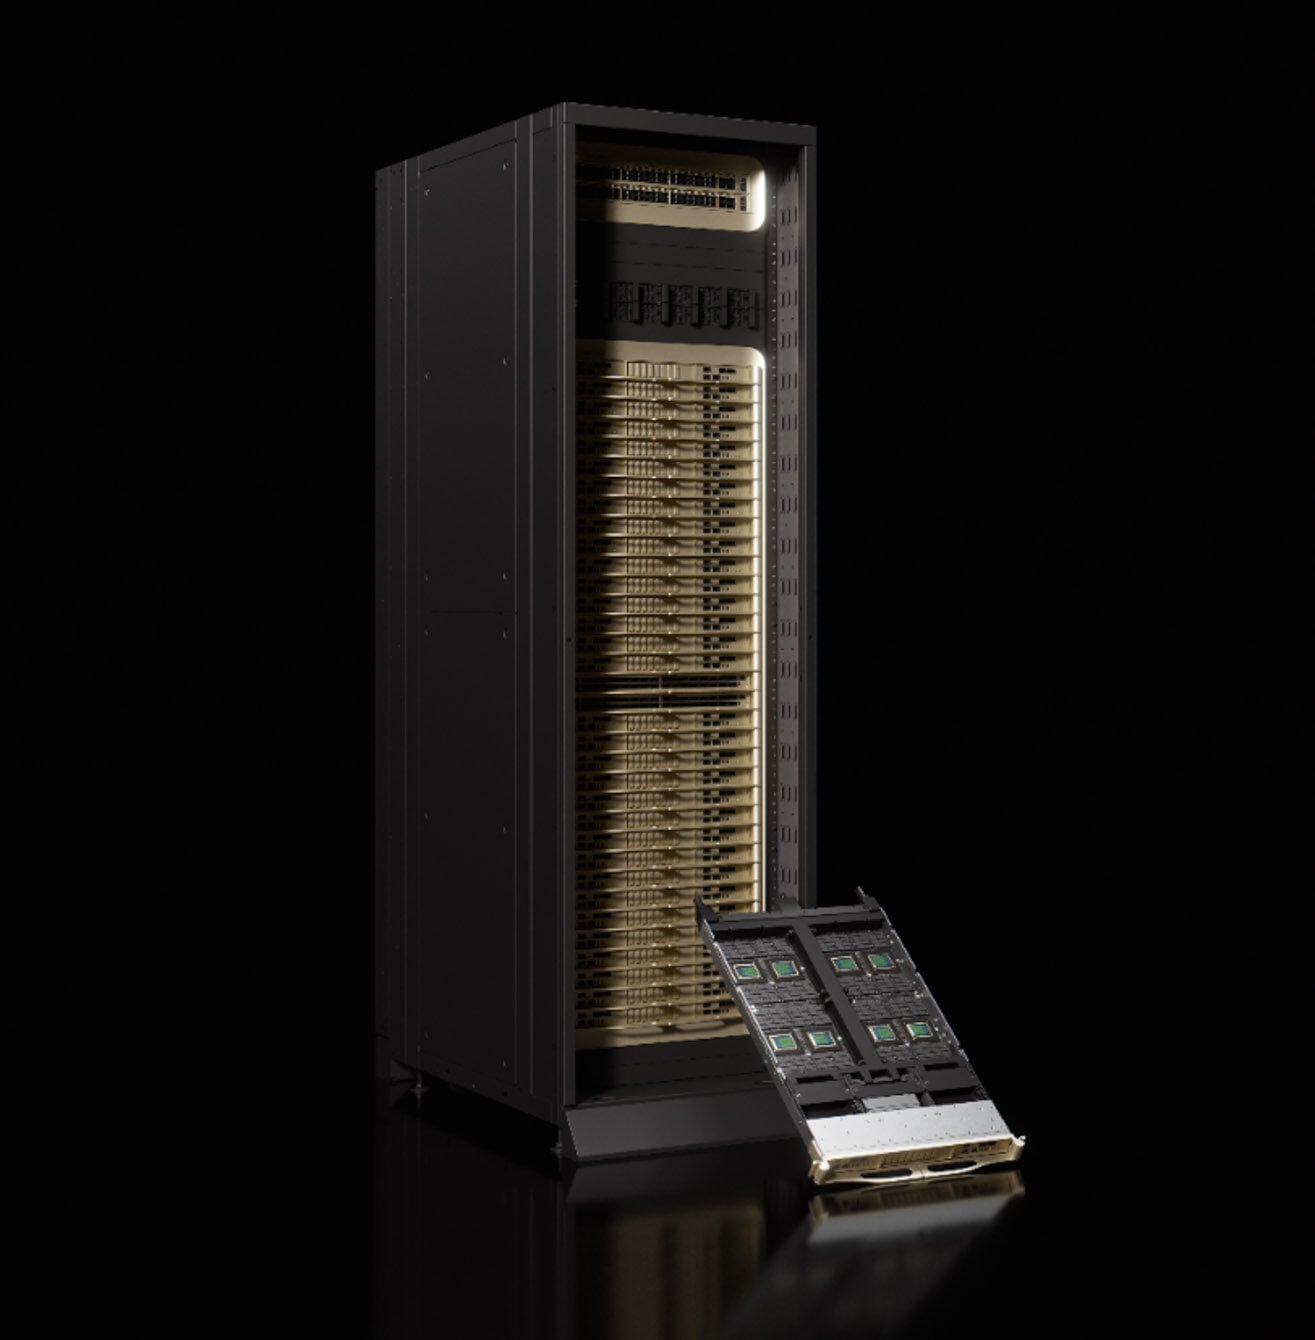
NVIDIA render of a Vera CPU rack with a compute tray pulled out in front, showing the processor sockets on the tray
AI  ◇  Enterprise

Supermicro NVIDIA Vera CPU Rack: 256 Vera CPUs, 400TB of LPDDR5X, and 22,500 Agent Sandboxes in a 208kW Liquid-Cooled 48U

Supermicro announced the NVIDIA Vera CPU rack today, a 48U, 100 percent liquid-cooled rack that holds 256 NVIDIA Vera CPUs, 22,528 cores, and 45,056 threads and that Supermicro rates for up to 22,500 concurrent agent sandboxes. It is the newest member of the Data Center Building Block Solutions (DCBBS) portfolio, built to run beside the

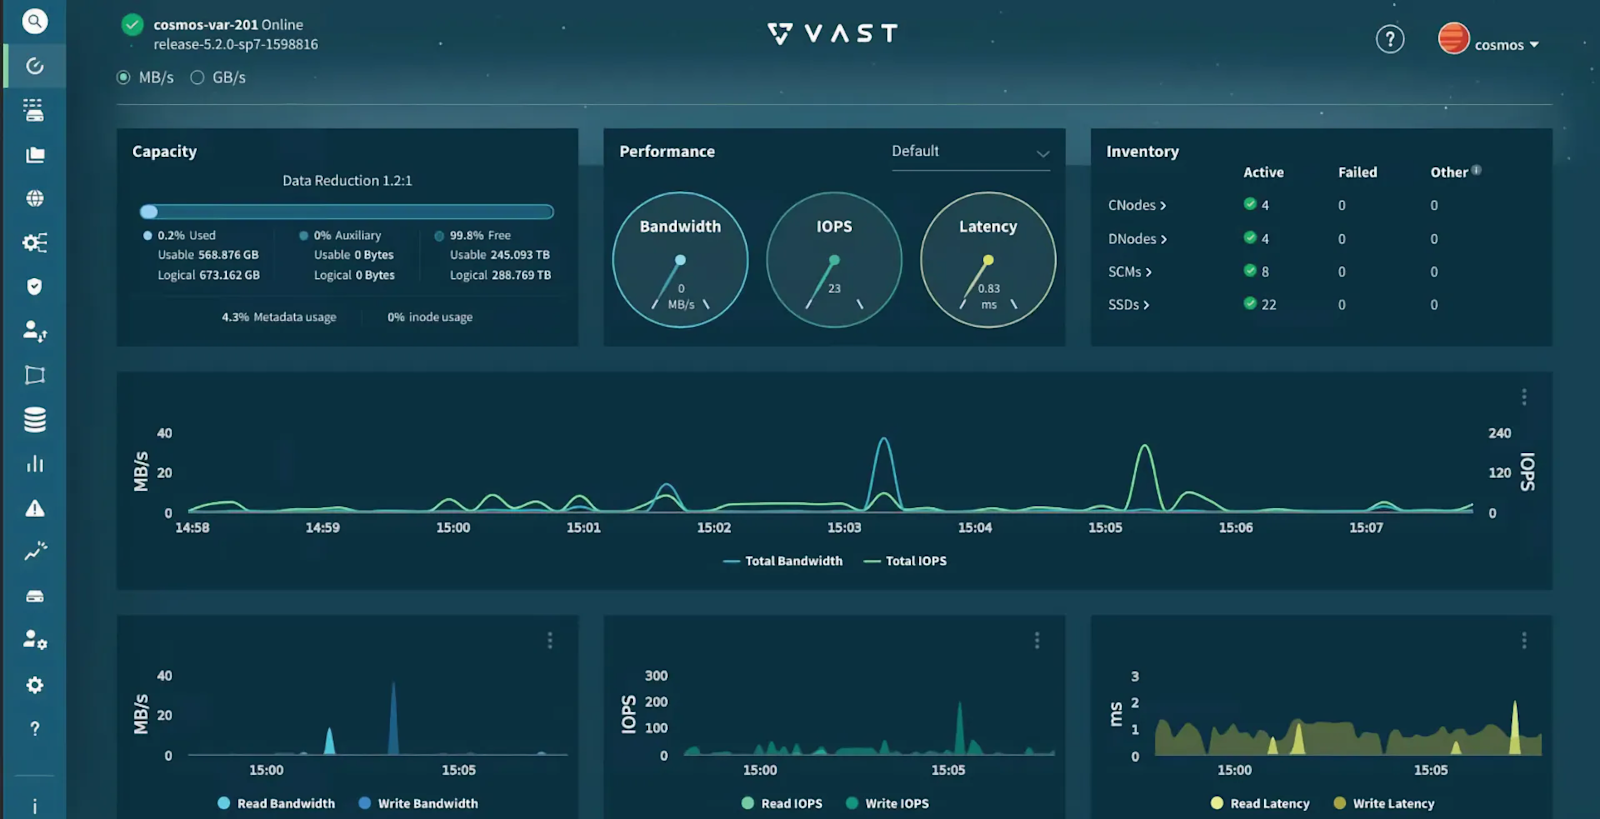
VAST Management System dashboard on a StorageReview lab cluster showing capacity, bandwidth, IOPS, and latency, the telemetry layer of the VAST Agent Sandbox Foundation Stack
AI  ◇  Enterprise

VAST Agent Sandbox Foundation Stack Puts NVIDIA OpenShell Sandboxes on Zero-Copy Clones and Logs Every Tool Call

VAST Data announced the Agent Sandbox Foundation Stack with NVIDIA at NVIDIA GTC Berlin, a reference architecture that runs NVIDIA NemoClaw agents inside NVIDIA OpenShell sandboxes on the VAST AI Operating System. OpenShell handles isolated execution and policy enforcement around each agent, and VAST handles the parts that have to outlive the sandbox: the agent’s

StorageReview LinkedIn Live graphic for What Extreme Density Enables at Scale with Bill Bollengier of Micron and Brian Beeler, with the Micron 6600 ION 245TB SSD in front of a Dell server
AI  ◇  Enterprise

Podcast #155: Micron’s 245TB SSD and What Extreme Density Enables at Scale

Brian hosted Bill Bollengier, Senior Director of Product Management at Micron, for a live podcast on LinkedIn on October 15, with Bill calling in from the floor of the OCP Global Summit. The subject was the Micron 6600 ION 245TB SSD and what a quarter petabyte per drive bay does to floor space, power budgets,

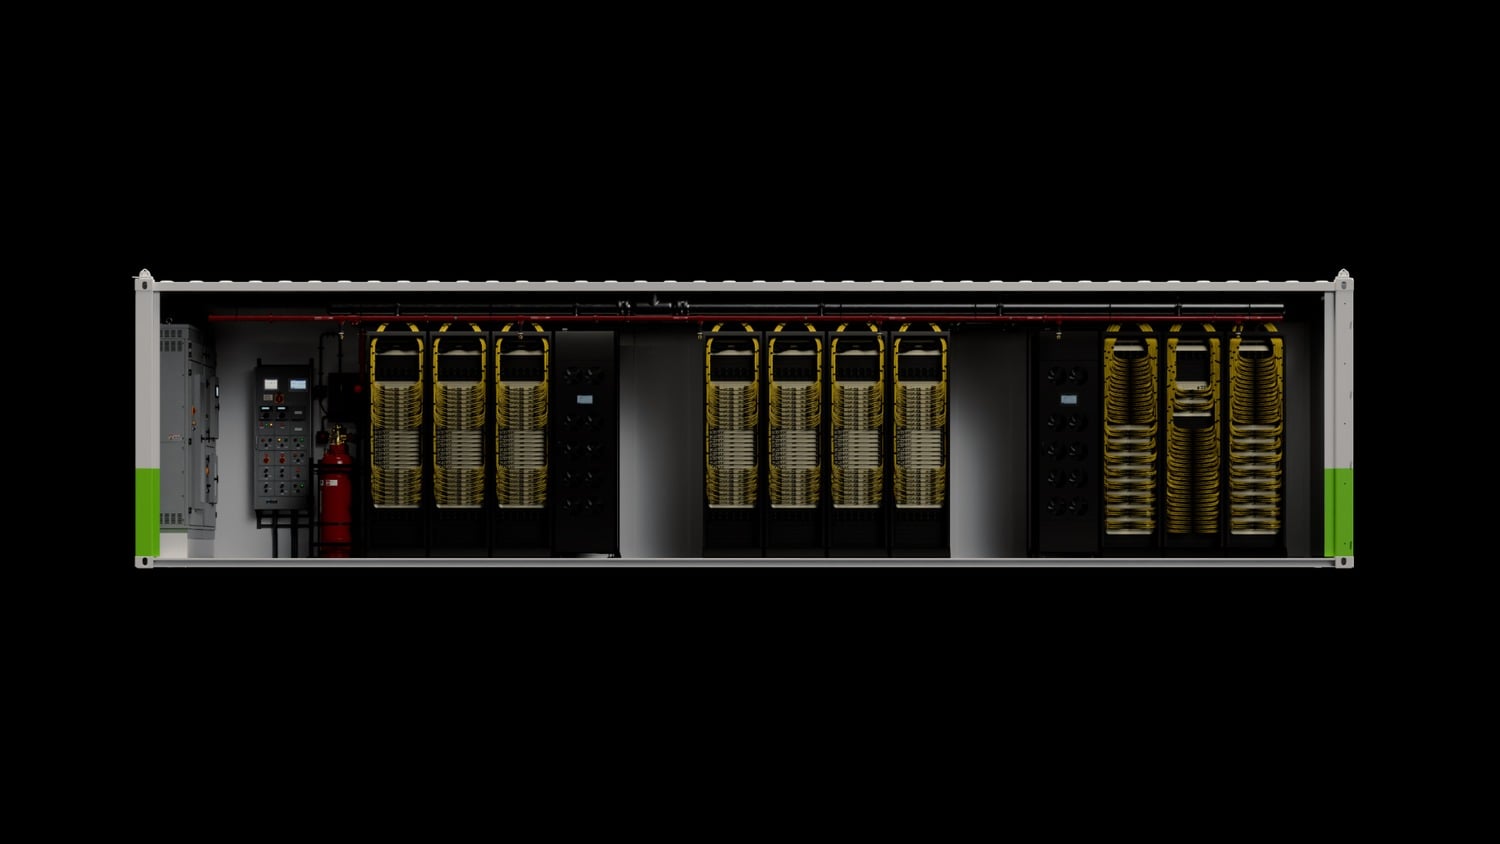
NVIDIA DSX POD render: a shipping container cut away to show three groups of Vera Rubin racks with yellow cabling, power distribution and fire suppression cabinets at the left end
AI  ◇  Enterprise

NVIDIA GTC Berlin: 14-Day DSX POD AI Factories, a 2.5x Substrate Buildout, and the OpenShell Reference Architecture

NVIDIA’s GTC Berlin announcements today span containerized Vera Rubin infrastructure, a 2.5x expansion of its substrate supply, and software for AI factory power management and agent security, along with telecom, autonomous vehicle, robotics, and healthcare programs. The headline number is a deployment target: NVIDIA says its new DSX POD reference design cuts an AI factory’s

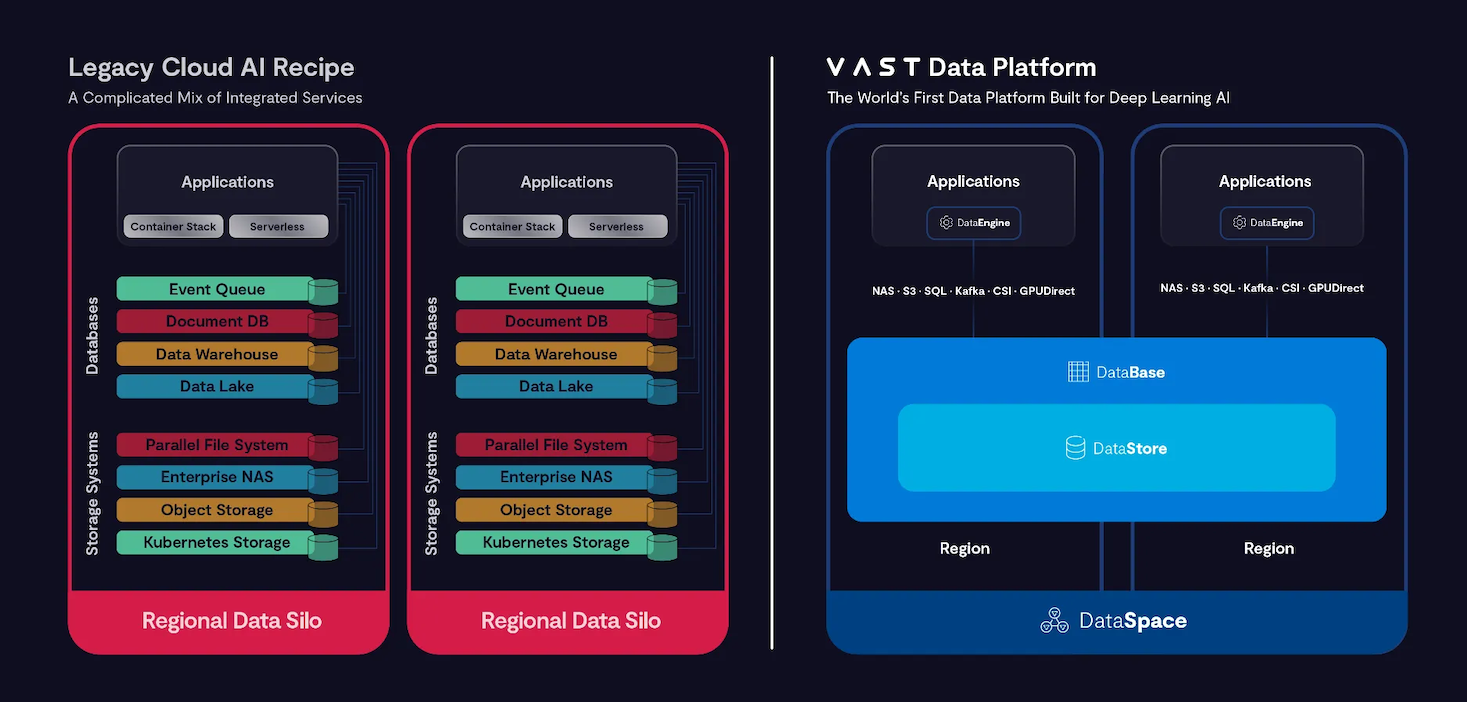
VAST Data diagram contrasting a legacy cloud AI stack of separate databases and storage systems in regional silos with the VAST Data Platform's DataBase, DataStore, and DataSpace layers spanning regions
AI  ◇  Enterprise

DeepL Deploys the VAST AI Operating System for Voice Translation Training, Expecting 3x the Capacity From Its Existing NVMe

VAST Data announced that DeepL is deploying the VAST AI Operating System as the data foundation for the research environments behind its written and real-time voice translation. Based on current deployment plans, DeepL expects roughly three times the storage capacity of the NVMe hardware it already runs, and it will use VAST’s SyncEngine to migrate

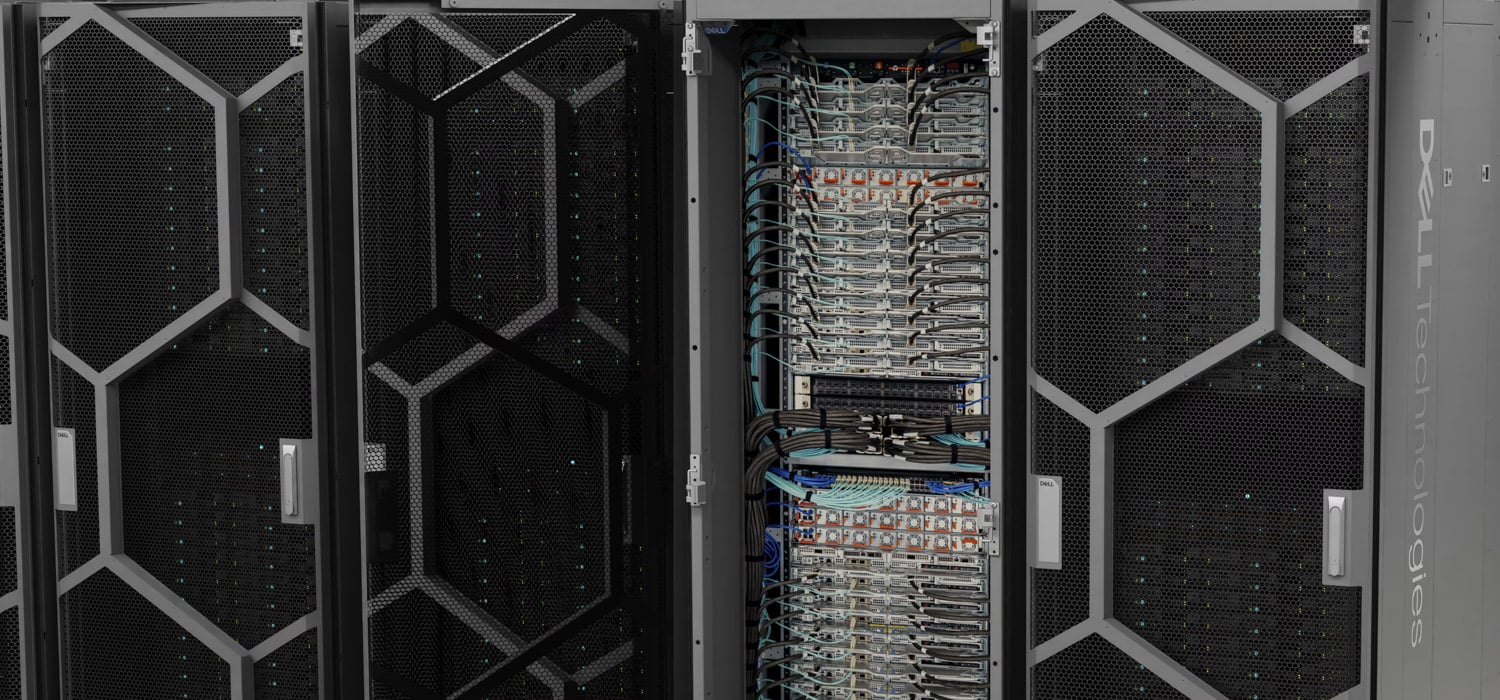
Dell Integrated Rack Scalable Systems cabinets with the center rack open to show a column of PowerEdge M7725 sleds and cabling, the rack-scale hardware behind the Dell AI Factory with NVIDIA
AI  ◇  Enterprise

Dell AI Factory with NVIDIA Adds a 256-CPU Vera Rack, a Groq 3 LPU Inference Rack, and a 64GB GB10 Desktop

Dell Technologies expanded the Dell AI Factory with NVIDIA today at NVIDIA GTC Berlin with a 48U PowerEdge M9882 rack holding 256 NVIDIA Vera CPUs for agentic workload execution, the PowerEdge XE9810 rack-scale inference system built on Groq 3 LPUs, an air-cooled two-socket Vera server, a 64GB Dell Pro Precision with GB10, and a set

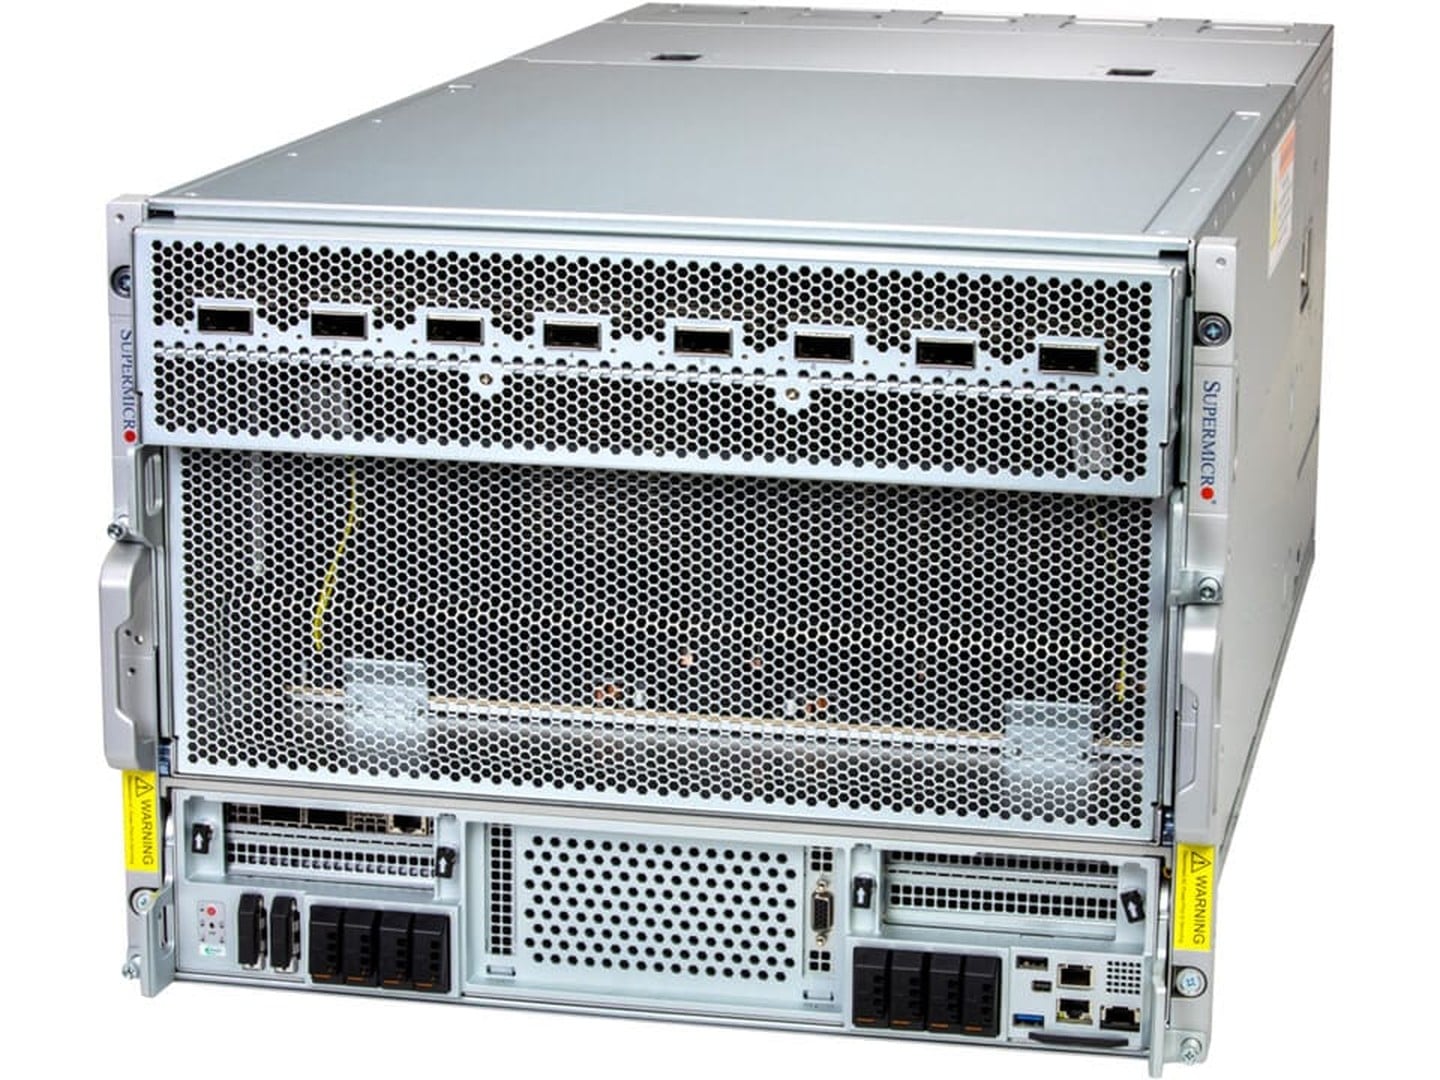
Supermicro AS-8126GS-NB3RT 8U GPU server with an NVIDIA HGX B300 eight-GPU baseboard, front view showing the E1.S and M.2 drive bays, one of the server classes behind the Nutanix private inference system
AI  ◇  Enterprise

Nutanix Private Inference System With Supermicro Puts Eight NVIDIA B300 Blackwell Ultra GPUs per Node Behind Dedicated NX Management and Storage Clusters, Ships Early 2027

Nutanix announced three collaborations today at NVIDIA GTC Berlin: a jointly engineered private inference system with Supermicro built on servers with eight NVIDIA B300 Blackwell Ultra GPUs per node, Day Zero support for NVIDIA Vera CPUs starting with NKP Bare Metal, and a multitenant stack with Netris that extends tenant isolation into the physical network.

Industrial robot arm picking a part from a table in a factory cell, CoreWeave's hero image for Physical AI Launchables
AI  ◇  Enterprise

CoreWeave Physical AI Launchables Put Isaac Sim, CARLA, and MuJoCo Behind One Command, With a Six-Layer Zero Trust AI Framework

CoreWeave launched Physical AI Launchables and the CoreWeave Zero Trust AI Framework today at NVIDIA GTC Berlin. Launchables is a catalog of tested, ready-to-run templates for robotics and autonomous vehicle tools, each started with one command, that pairs environments for NVIDIA Isaac Sim, CARLA, MuJoCo, NVIDIA AlpaSim, and NVIDIA Cosmos 3 with coding-agent skills tuned

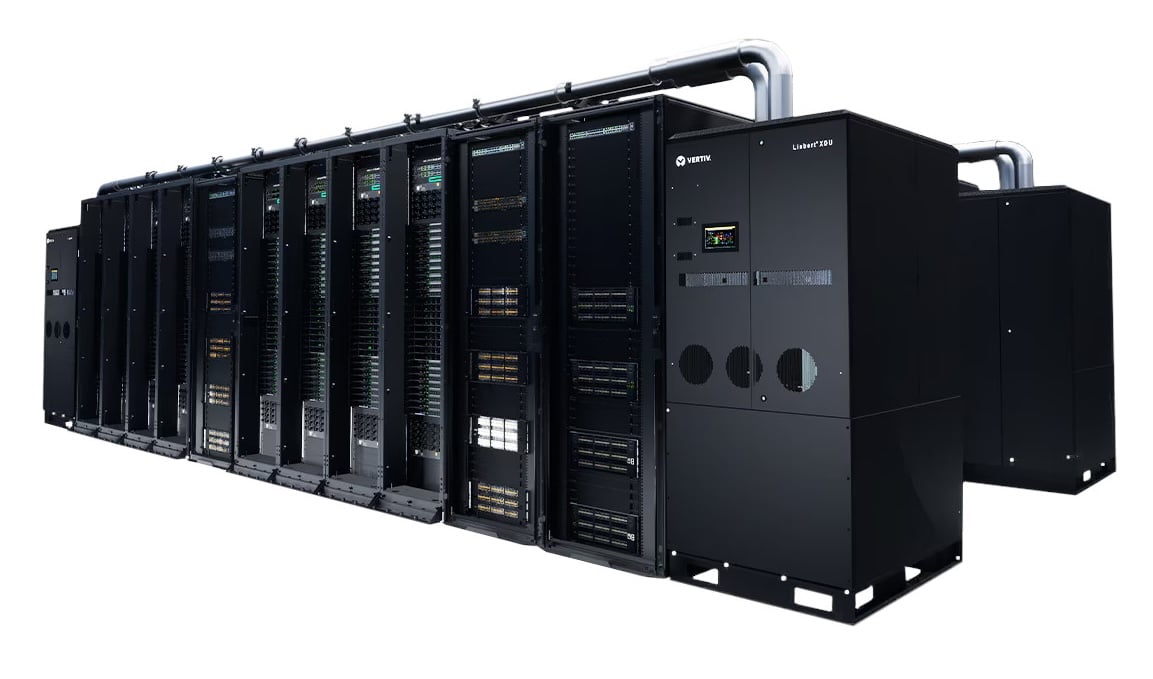
HPE AI Factory with NVIDIA render of a row of compute racks with Vertiv Liebert XDU coolant distribution units at the end of the row
AI  ◇  Enterprise

HPE Private Cloud AI Adds MCP Servers, Mixed H200 and RTX PRO 6000 Clusters, and a 256-CPU NVIDIA Vera Rack

HPE announced updates to HPE AI Factory with NVIDIA today at NVIDIA GTC Berlin, and most of the changes land in HPE Private Cloud AI. Developers, independent software vendors, and AI agents get governed access to the platform’s inference, models, and pipelines through production APIs and Model Context Protocol (MCP) servers, clusters can now mix