StorageReview.com
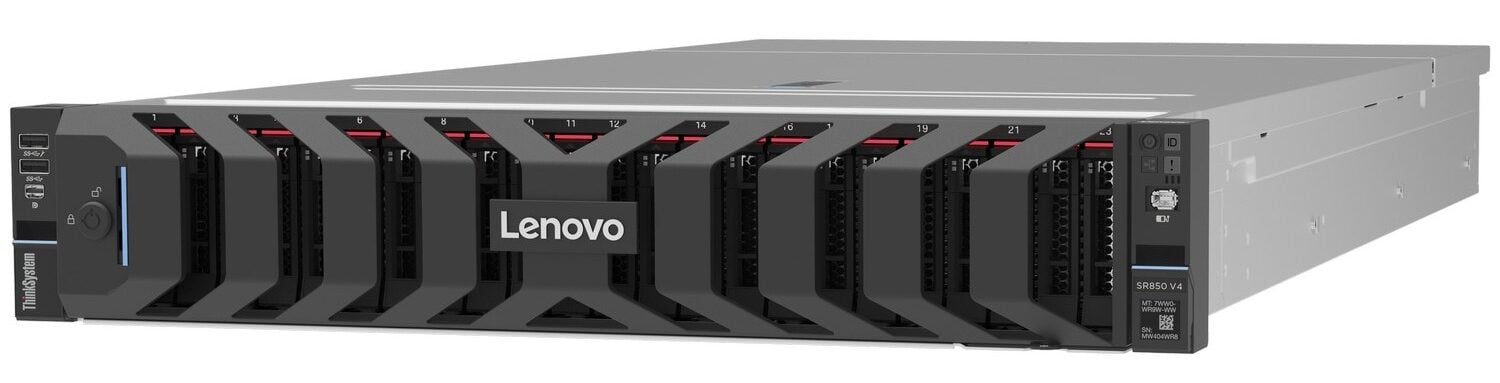
Lenovo ThinkSystem SR850 V4 2U four-socket server front view with the security bezel and 24 hot-swap drive bays, Lenovo product image
Enterprise  ◇  Server

Lenovo ThinkAgile VX850 V4 Takes On In-Memory Virtualization With New Deploy Tiers and Four-Hypervisor Express Bundles

Lenovo has added the ThinkAgile VX850 V4 to its virtualization lineup, a four-socket node it describes as purpose-built for highly virtualized and demanding in-memory workloads, and paired the launch with a three-tier deployment service framework and a set of pre-validated Top Choice Express bundles spanning Microsoft, Red Hat, SUSE, and Nutanix. The announcement follows Lenovo’s
TrueNAS and Proxmox logos on the TrueNAS Proxmox Plugin announcement graphic with the line Plugin Now Available on GitHub
Enterprise  ◇  Software

TrueNAS Proxmox Plugin Turns Every VM Disk Request Into an Automated zvol Over iSCSI or NVMe/TCP

TrueNAS has released a native Proxmox VE storage plugin that lets Proxmox provision and manage VM disks directly on TrueNAS systems. A disk requested in Proxmox becomes an OpenZFS zvol on TrueNAS 25.10 or later, published as an iSCSI LUN or an NVMe/TCP namespace, and the plugin handles creation, snapshots, resizing, migration, and deletion from

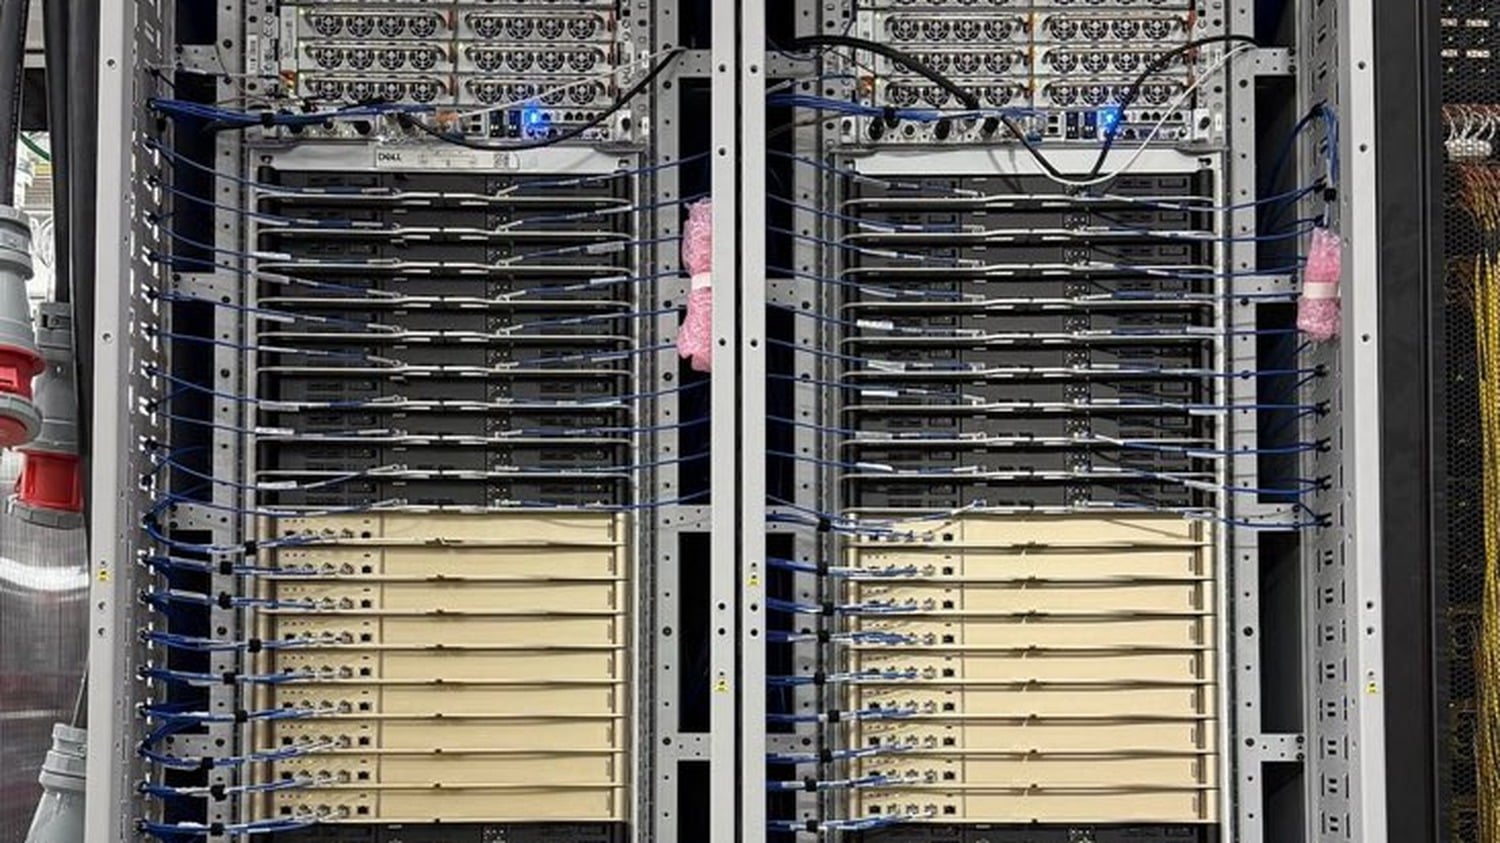
Two Dell-built NVIDIA Vera Rubin NVL72 racks in a CoreWeave data center, cropped to the compute and NVLink switch trays, photo courtesy of CoreWeave
Cloud  ◇  Enterprise

CoreWeave Deploys Multi-Rack Vera Rubin NVL72 Cluster: Hundreds of Rubin GPUs, 1.6 Tb/s Per GPU, and a No-Fee Archive Tier

CoreWeave has deployed a multi-rack NVIDIA Vera Rubin NVL72 cluster on CoreWeave Cloud, connecting hundreds of Rubin GPUs into a single scale-out environment aimed at agentic AI workloads. Each Dell-built rack carries 72 Rubin GPUs, 36 Vera CPUs, NVLink 6 as the scale-up fabric, BlueField-4 DPUs, and two ConnectX-9 SuperNICs per GPU, and the racks

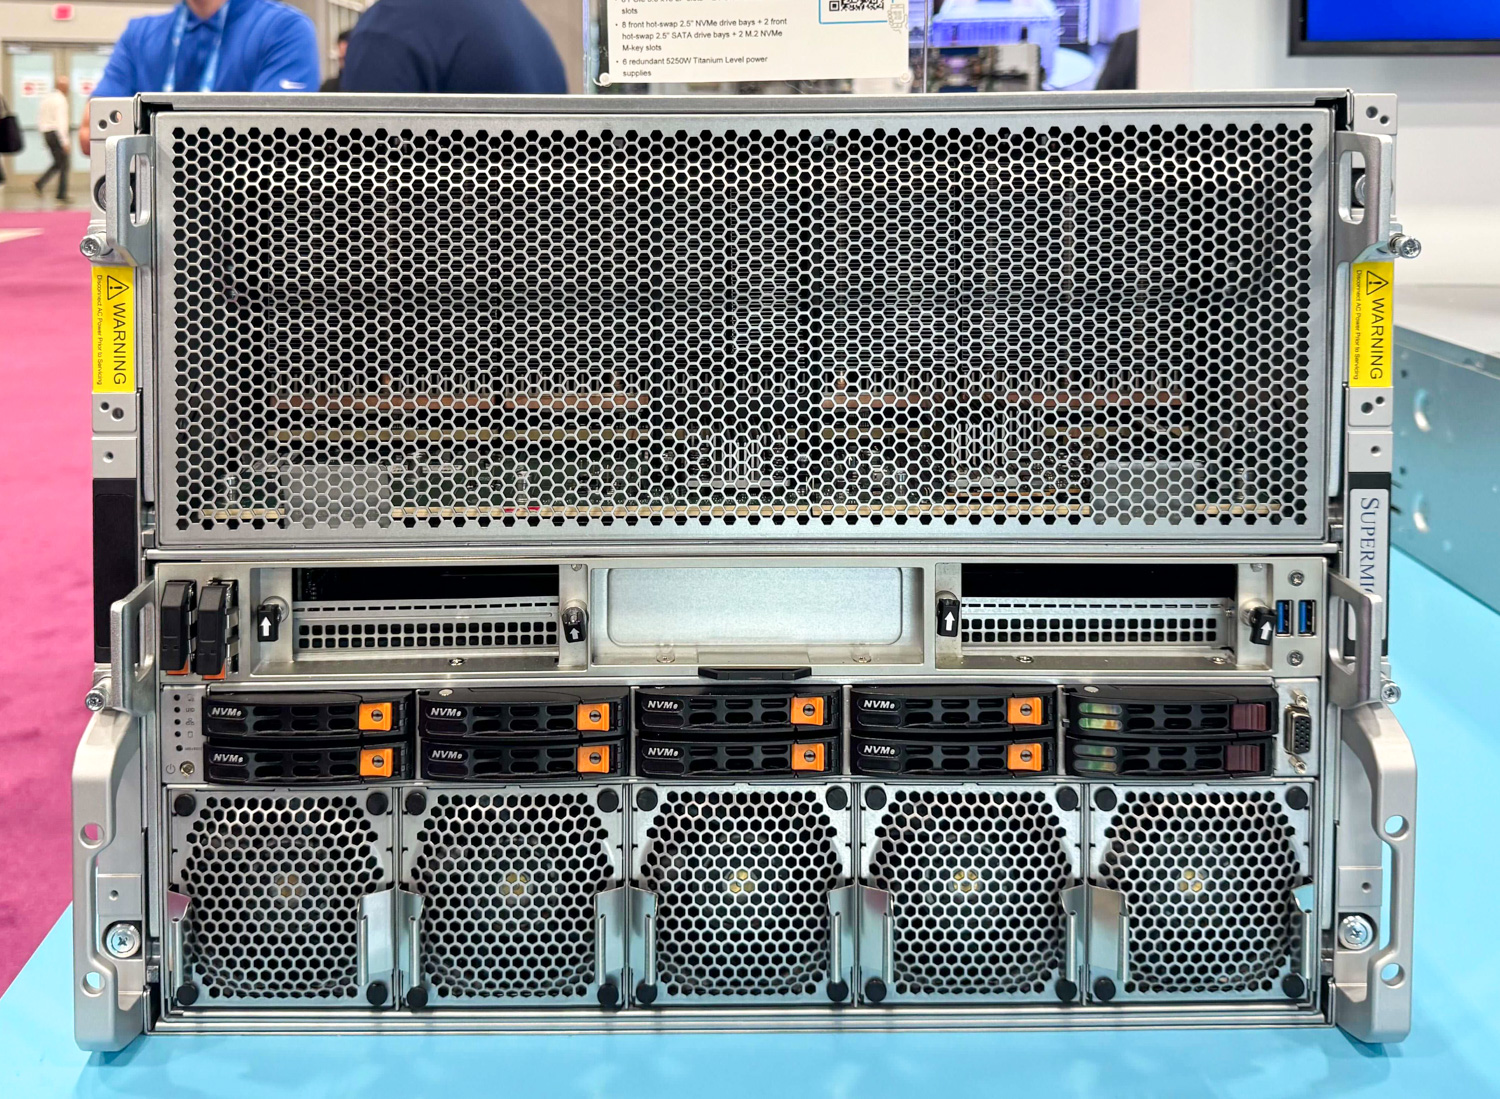
Supermicro H14 server with AMD Instinct MI350X GPUs, front view showing the fan wall and NVMe drive bays
AI  ◇  Enterprise

MLPerf Inference v6.1: 5.7x Per-Accelerator Gains, a 512-GPU Run, and Vera Rubin’s First Peer-Reviewed Numbers

MLCommons has published MLPerf Inference v6.1, and the round sets a participation record with 30 submitting organizations and 486 datacenter and edge results. Two new tests join the suite: an End-to-End RAG pipeline for the datacenter and an Edge Agentic Inference benchmark for single-user devices, and the results carry the first peer-reviewed numbers for NVIDIA’s

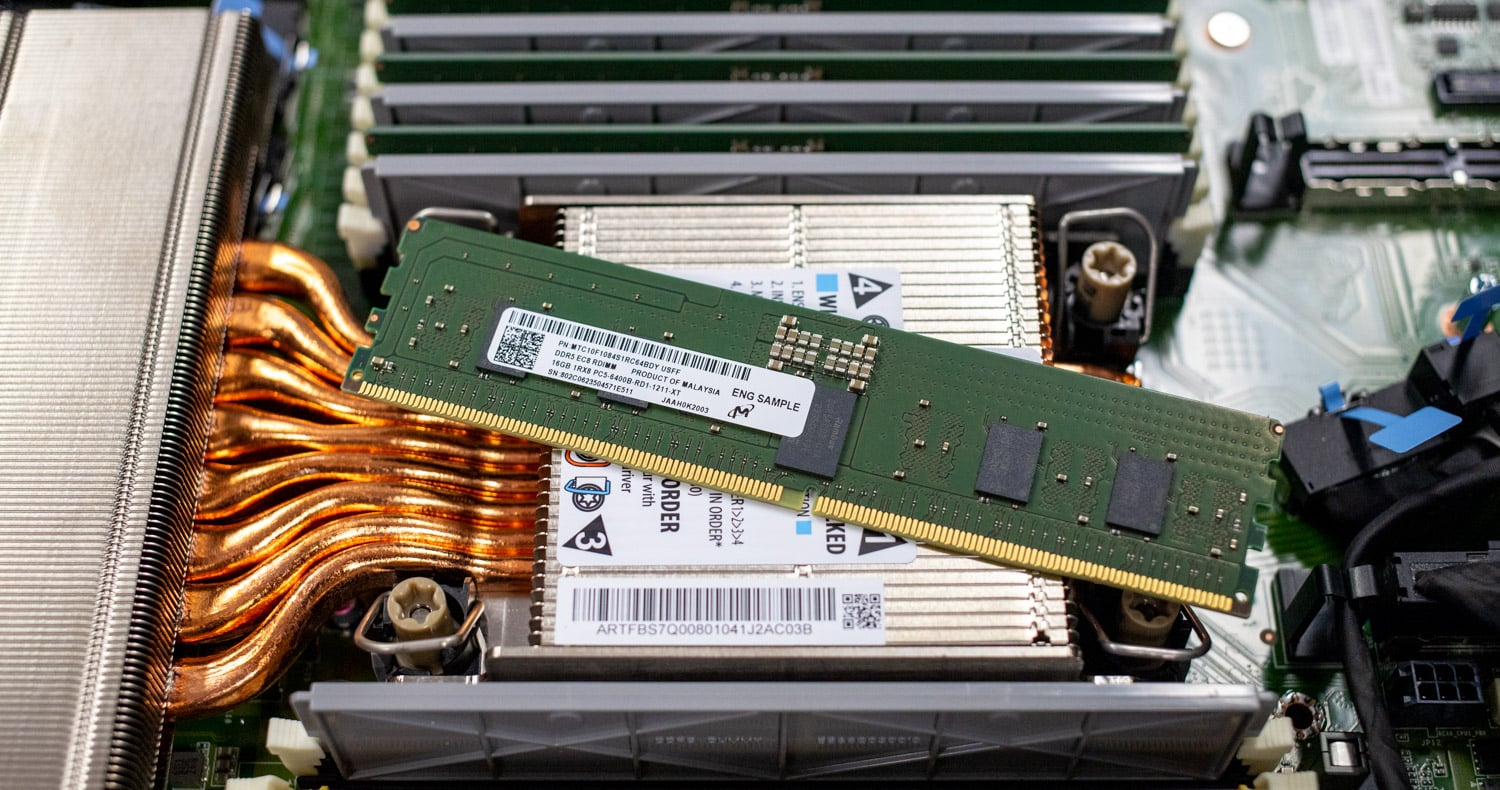
Micron DDR5 RDIMM resting on server CPU heatsinks, photo courtesy of Micron
Enterprise  ◇  Server

Micron Shows off 512GB DDR5 RDIMM: 12TB per Dual-Socket Server at 9,200 MT/s, Volume Production in 2H 2027

Micron has demonstrated a 512GB DDR5 RDIMM running on multiple server platforms, which it calls the world’s first module at that capacity, and says AMD and Intel are both validating it for their next-generation server platforms. The module is rated for speeds up to 9,200 MT/s, and in a 24-slot dual-socket server it puts 12TB

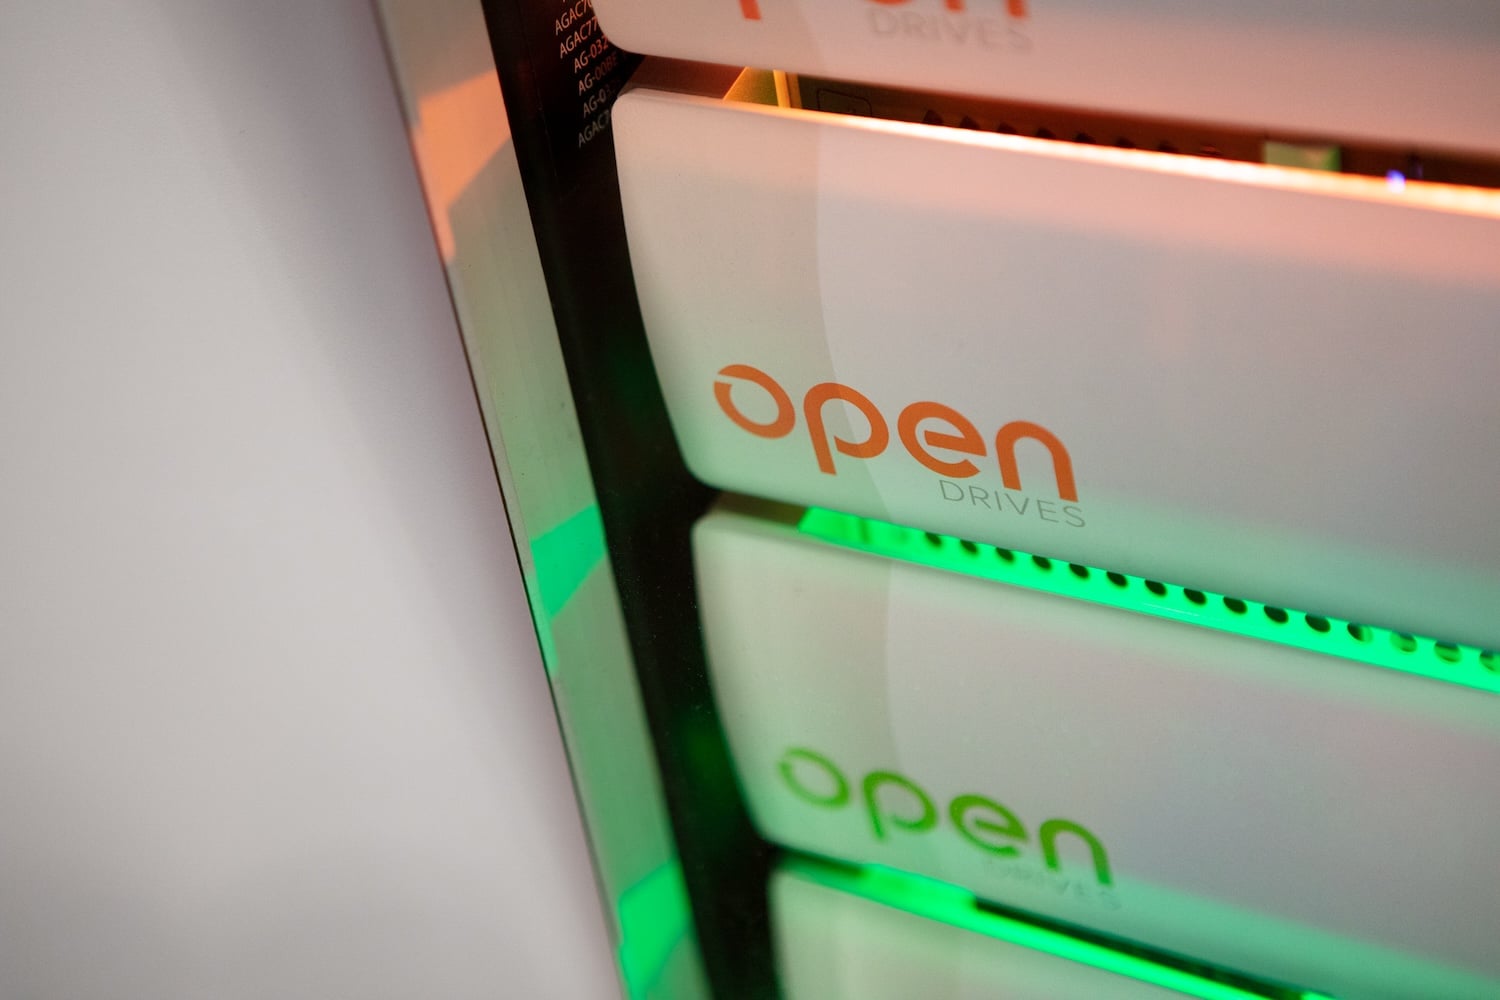
Close-up of a stack of OpenDrives storage chassis with orange OpenDrives logos on the front panels and green status lighting between the units
Enterprise  ◇  Enterprise Storage

OWC Acquires OpenDrives, Adding Atlas, Astraeus, and Edge to the Jellyfish Shared Storage Line

Other World Computing (OWC) has acquired OpenDrives, the Los Angeles software-defined storage company whose Atlas platform has sat behind Hollywood studios, post houses, and live broadcast networks since 2011. The deal brings OpenDrives’ Atlas, Astraeus, and Edge platforms into OWC’s shared storage portfolio alongside the Jellyfish line, and OWC says it extends that line into

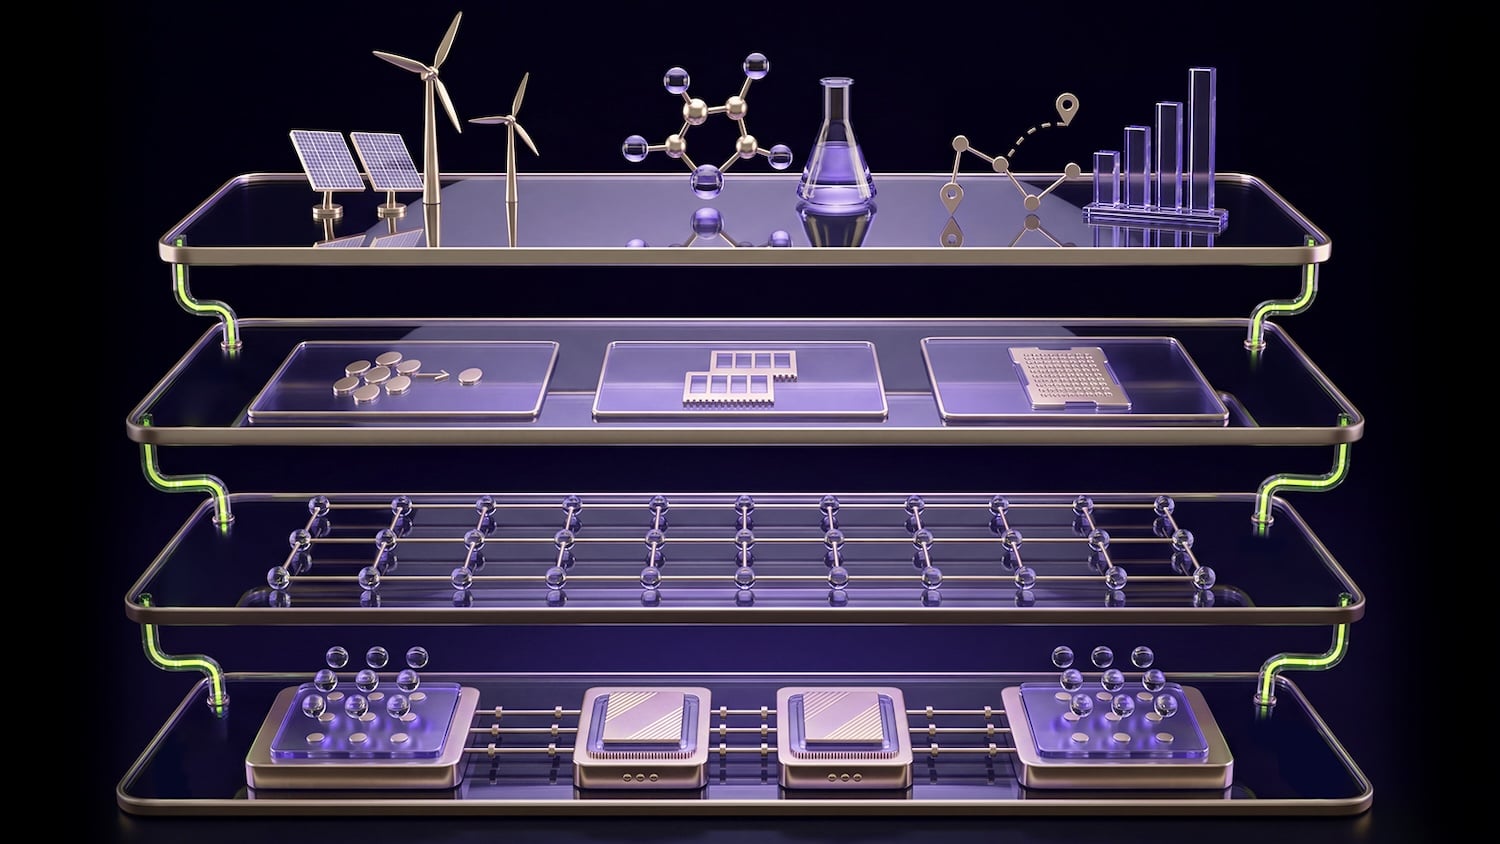
NVIDIA CUDA-Q Logical concept render showing four stacked layers from physical qubits and control hardware at the bottom up to applications such as molecular modeling and energy at the top
AI  ◇  Enterprise

NVIDIA CUDA-Q Logical Debuts With a 7x Fermilab Speedup and a 10x Cut in Diraq’s Qubit Estimate

NVIDIA has added CUDA-Q Logical to its open-source CUDA-Q platform, an orchestration layer for building applications that run on fault-tolerant quantum computers, and it arrives with two numbers that are interesting. Fermilab says the tool cut a fault-tolerant algorithm design cycle from five months to three weeks, and Iceberg Quantum used it to show that

AI  ◇  Enterprise

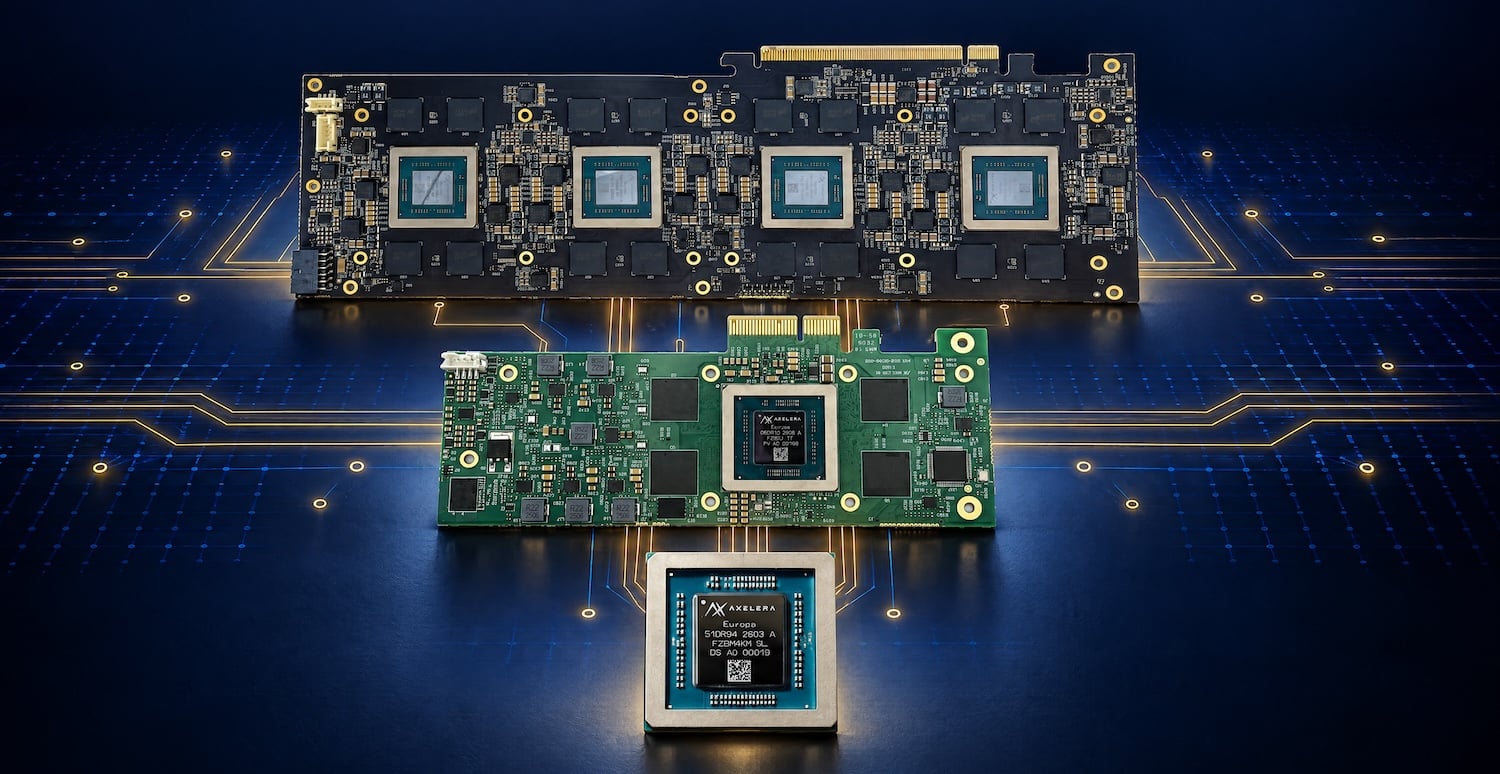
Axelera Europa Ships: 629 TOPS at 45W Per AIPU, in Validated Dell XE5 and Supermicro Servers

Axelera AI is shipping Europa, the second-generation AI Processing Unit (AIPU) it has been previewing since last year, and it’s launching with validated servers from Dell and Supermicro attached. The Eindhoven company’s pitch is inference on infrastructure the customer controls: agentic systems, vision-language models, generative AI, and computer vision running in a standard rackmount server

Abstract illustration of a glowing processor on a circuit board linked to clusters of data blocks, CTERA marketing art for its AI workflow announcements
Enterprise  ◇  Enterprise Storage

Just 4.4% of Enterprise NAS Capacity Is Active, CTERA Cold Data Storage Report Finds

CTERA has published The Cold Data Storage Report, an analysis of 16 petabytes of live production data across 856 file-share discovery scans in enterprise NAS environments, including regulated industries, and the headline number is that just 4.4% of stored capacity is actively used, which the report page defines as modified within a 90-day window. The