

Google added two systems to its eighth-generation TPU lineup: TPU 8tx, a confidential computing system built on TPU 8t silicon, and TPU 8i Max, which puts two TPU 8i chips on a single package for long-context inference. They join the TPU 8t training chip and TPU 8i inference chip Google introduced at Cloud Next in April, and Google says this is the first time it has introduced four TPU systems in a single year.
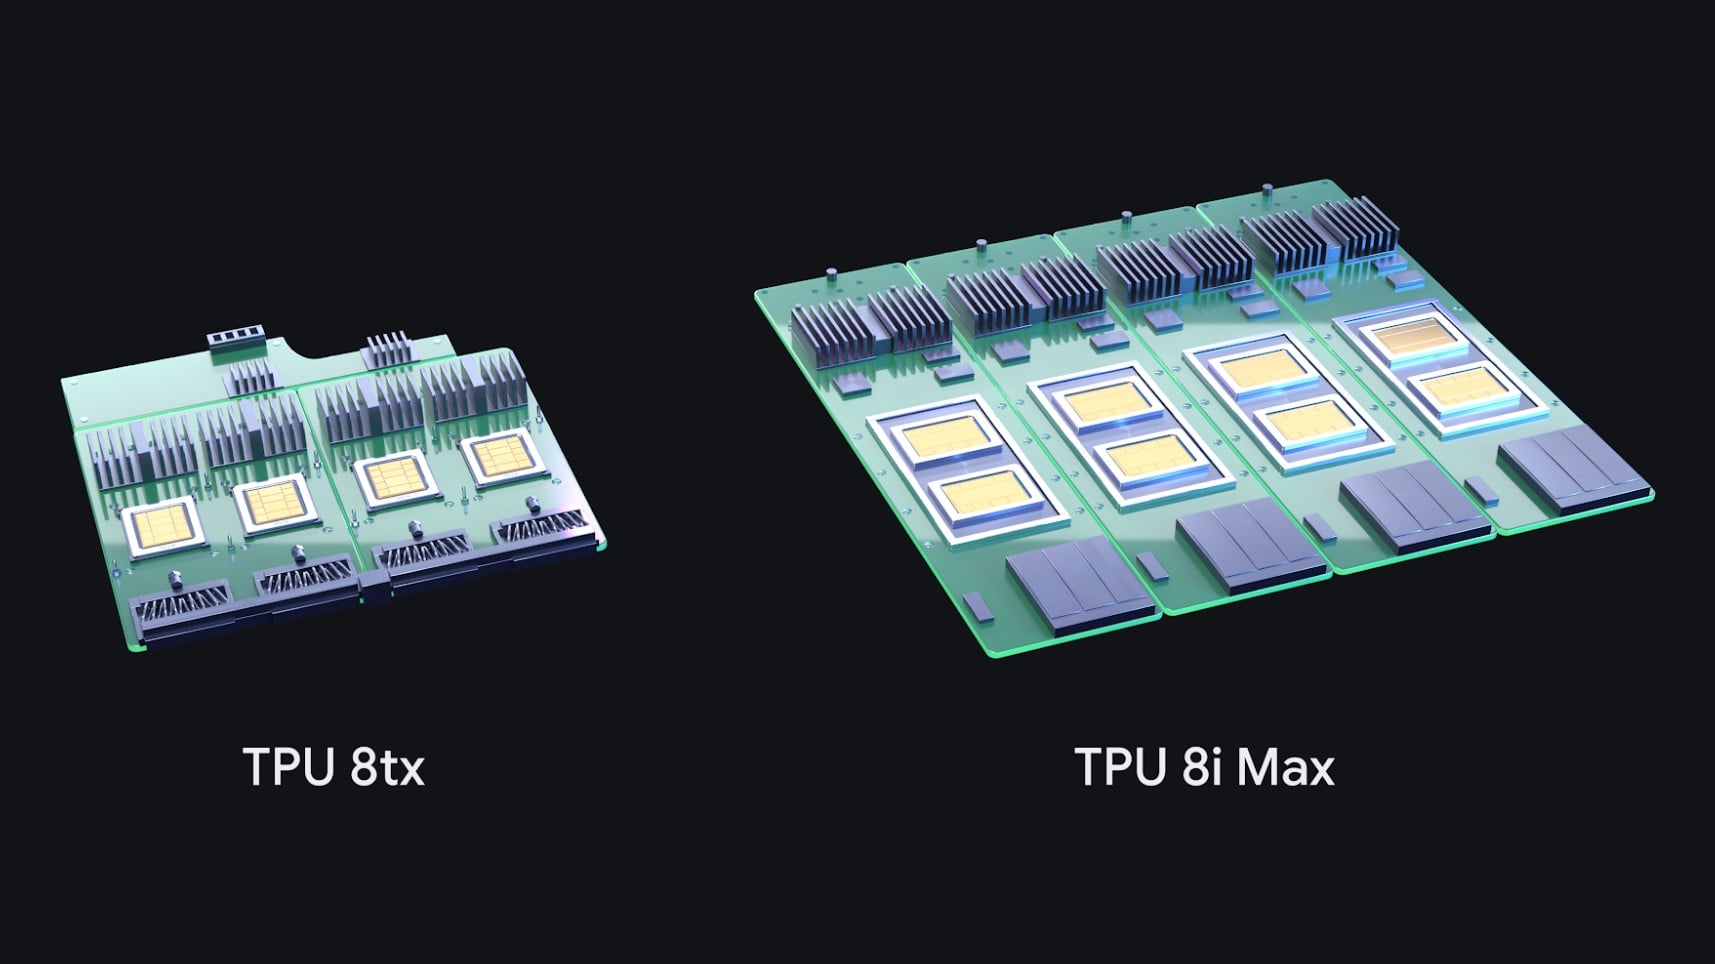
Google describes the two additions as new systems built around existing chips, changing the packaging, high-speed memory, networking, and security around the silicon to fit a workload, and credits that modular approach with delivering specialized configurations in months. TPUs now have nearly 100 customers, according to Google, including frontier labs, trading firms, retailers, and universities, and some customers can now deploy TPUs directly in their data centers.
TPU 8tx: Confidential Computing on TPU 8t Silicon
TPU 8tx uses the same silicon as TPU 8t, pairs it with 5th Generation AMD EPYC host CPUs, and builds confidential computing into the hardware so data and model weights stay protected and isolated while in use. Google lists PCIe link encryption, cryptographic attestation, and secure memory enclaves among its security features, and it is aiming the system at regulated enterprises and governments that run frontier or proprietary models and agents alongside sensitive data.

TPU 8tx also adopts the low-latency Boardfly network Google built for TPU 8i, which Google says delivers up to 2x lower latency than TPU 8t with a near-zero performance penalty. Google positions it for secure inference and small-scale training, so a team can fine-tune on private data, distill a large model into a smaller one, and train agents through reinforcement learning without moving sensitive data between separate clusters.
TPU 8i Max: Two Inference Chips per Package
TPU 8i Max targets memory bandwidth for workloads such as dozens of agents working across an entire codebase or hours of video. Google combined two TPU 8i chips on one package, doubling compute, on-chip SRAM, and HBM bandwidth over TPU 8i. Google listed 384MB of SRAM for TPU 8i at launch, so the doubled figure works out to 768MB per 8i Max package, and Google has not stated the package’s HBM capacity. Because 8i Max fits twice the silicon in the existing rack footprint, Google says it delivers more compute per square foot and per watt.

Google now maps the four eighth-generation systems to stages of agent work: TPU 8t for scale-up training, TPU 8i for low-latency reasoning, TPU 8tx for confidential computing, and TPU 8i Max for massive context windows and the highest compute density per rack. Google has not said when TPU 8tx and TPU 8i Max will reach Google Cloud customers or published pricing for either system.

TPU Sync, Cloud Pathways, and GKE Dynamic Slicing
Google also open-sourced TPU Sync, a C++ library that treats chip HBM, host DRAM, shared storage, and the data center network as a single memory hierarchy. It tiers KV caches off the chip, streams context from prefill nodes to decode nodes, and synchronizes reinforcement learning weights from trainers to samplers. Google says TPU Sync cuts KV transfer latency by more than 90 percent and reduces time to first token by an average of 90 percent on open-weight mixture-of-experts models of 235B to 480B parameters.
Cloud Pathways, the Google DeepMind runtime behind Gemini, is now generally available on Google Kubernetes Engine. It uses a single controller to orchestrate TPU systems across multiple slices for pretraining, reinforcement learning, and multihost inference, and keeps long-running jobs going through hardware disruptions with sub-minute slice hot-swapping and elastic resharding.
GKE dynamic slicing, also generally available, uses optical circuit switching to assemble TPU cubes into larger topologies or split them into smaller isolated workloads without recreating node pools. Google says it cuts job startup times by up to 5x and speeds fault recovery by up to 4.5x. A TPU agent suite in preview plugs into coding tools such as Claude Code, Cursor, and Google Antigravity to onboard workloads, diagnose bottlenecks, and autotune kernels, and a new open-source XLA Serving Engine serves Python-trained models from a C++ runtime across TPUs, GPUs, and CPUs.



 Amazon