

NVIDIA has added a 64GB unified-memory configuration of the DGX Spark, starting at $4,999 and sold exclusively through Acer, ASUS, Dell, Gigabyte, HP, and MSI from October 23. The new SKU carries the same GB10 Grace Blackwell Superchip, ConnectX-7 networking, DGX OS, and NVIDIA AI software stack as the 128GB model. On its own, NVIDIA says the 64GB unit runs models up to 100 billion parameters for local inference, fine-tuning, and agent workflows without sending data to the cloud.
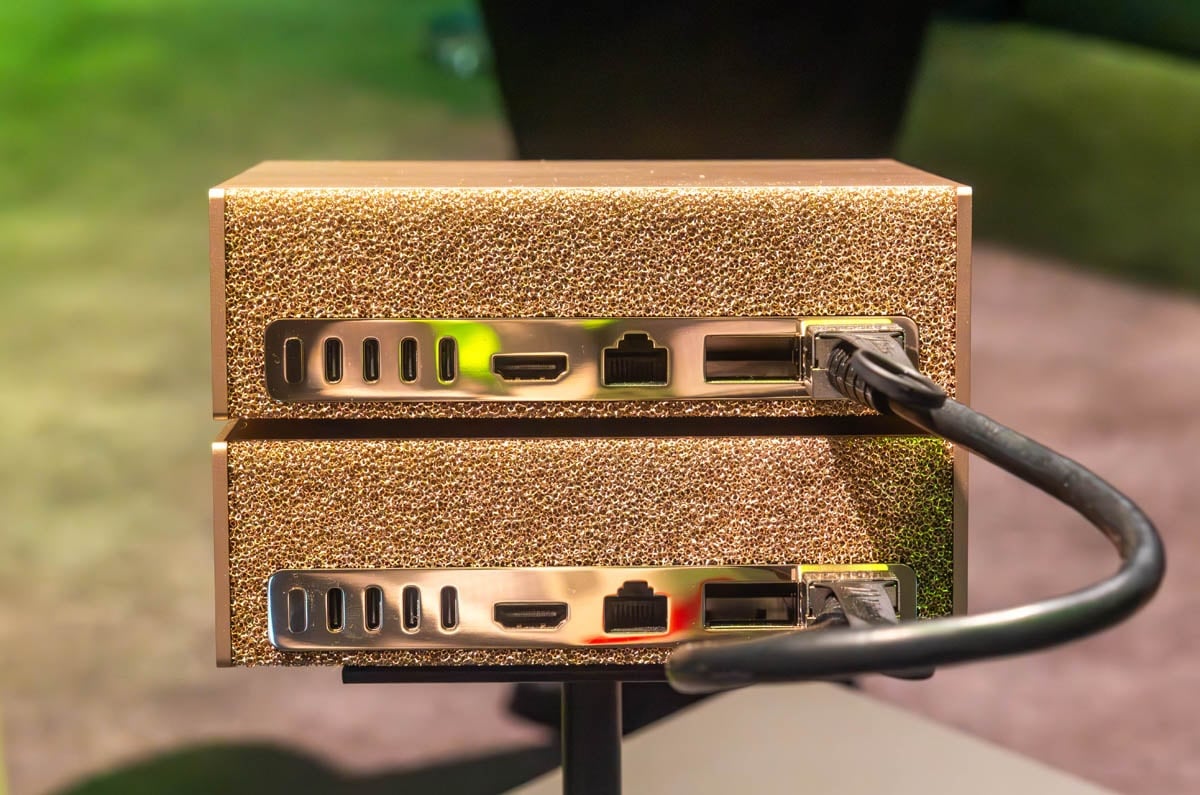
Two 64GB Sparks for One 128GB Cluster
The pitch for the cheaper box (compared to market rates of the larger model) is that two of them in a cluster do pretty well. Each DGX Spark has an onboard ConnectX-7 NIC, so a pair connects directly over a QSFP cable on a 200GbE link, with no switch in between. The NVIDIA Sync Cluster Assistant handles discovery, validates the device configuration, and sets up the ConnectX-7 network. Two 64GB units pool to 128GB of unified memory, which NVIDIA says is enough to run models up to 200 billion parameters.
NVIDIA’s internal numbers for the pairing use Qwen3.8 27B: two clustered 64GB systems delivered up to 1.7x the performance of a single 128GB system. Because each node runs the same CUDA libraries, inference engines, and DGX OS image, a workload spans both units without rebuilding the software environment. Supported inference frameworks include llama.cpp, Ollama, vLLM, and LM Studio. NVIDIA has a short video on connecting two Sparks with NVIDIA Sync.
We ran a distributed inference cluster across Dell, Gigabyte, and HP DGX Spark units, and more recently put shared storage behind a Spark cluster over 100GbE. The 64GB SKU lowers the entry price for that kind of setup, with the trade-off that a single unit now holds half the memory of the original.
NVIDIA Sync Model Launcher Arrives End of October
The second half of the announcement is software. The NVIDIA Sync Model Launcher, due at the end of October, downloads and launches a model across a single Spark or a clustered pair, with Qwen3.8 27B as the example, and exposes the resulting endpoint to developer machines on the network. It can also set up OpenCode against that model so developers can code from a browser with the Spark cluster doing the inference.
The 64GB systems ship with the same software as the 128GB model: DGX OS, CUDA-X AI libraries, the NVIDIA Agent Toolkit, Nemotron open models, and runtimes including Ollama, vLLM, and PyTorch with CUDA. NVIDIA positions the box as a local platform for agents, inference, fine-tuning, data science, and edge development, and the ConnectX-7 port means a second unit can be added later. For agent builders, NVIDIA points to its playbooks for NemoClaw, OpenClaw, Hermes Agent, and OpenShell on build.nvidia.com as the starting points.


 Amazon