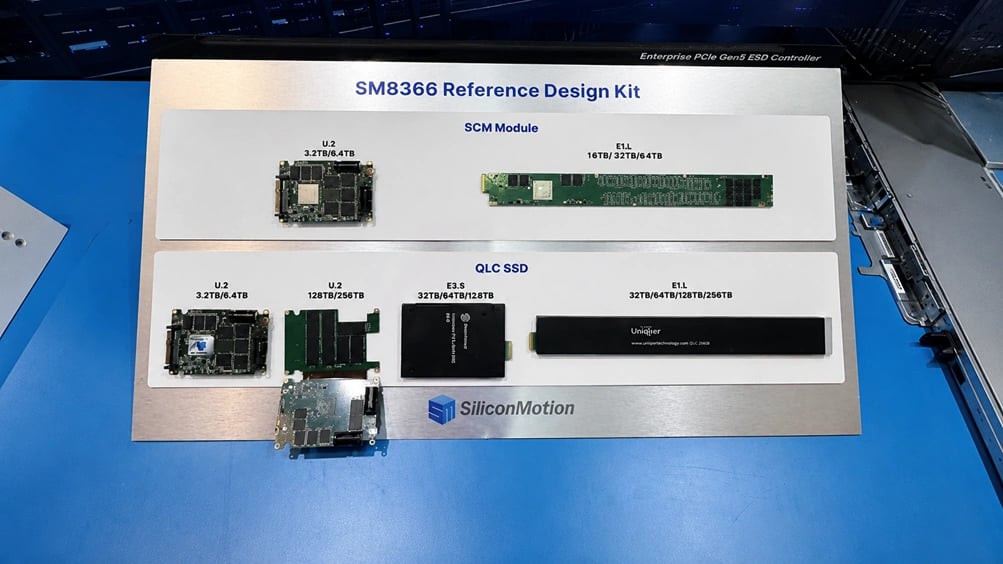
At FMS 2026, Silicon Motion introduced the MonTitan SSD Reference Design Kit (RDK), a platform built around the company’s next-generation PerformaShape technology. The design targets Agentic AI infrastructure, where enterprise SSDs can provide a persistent memory layer for KV cache offload and autonomous AI agents. Agentic AI workloads place different demands on storage than conventional
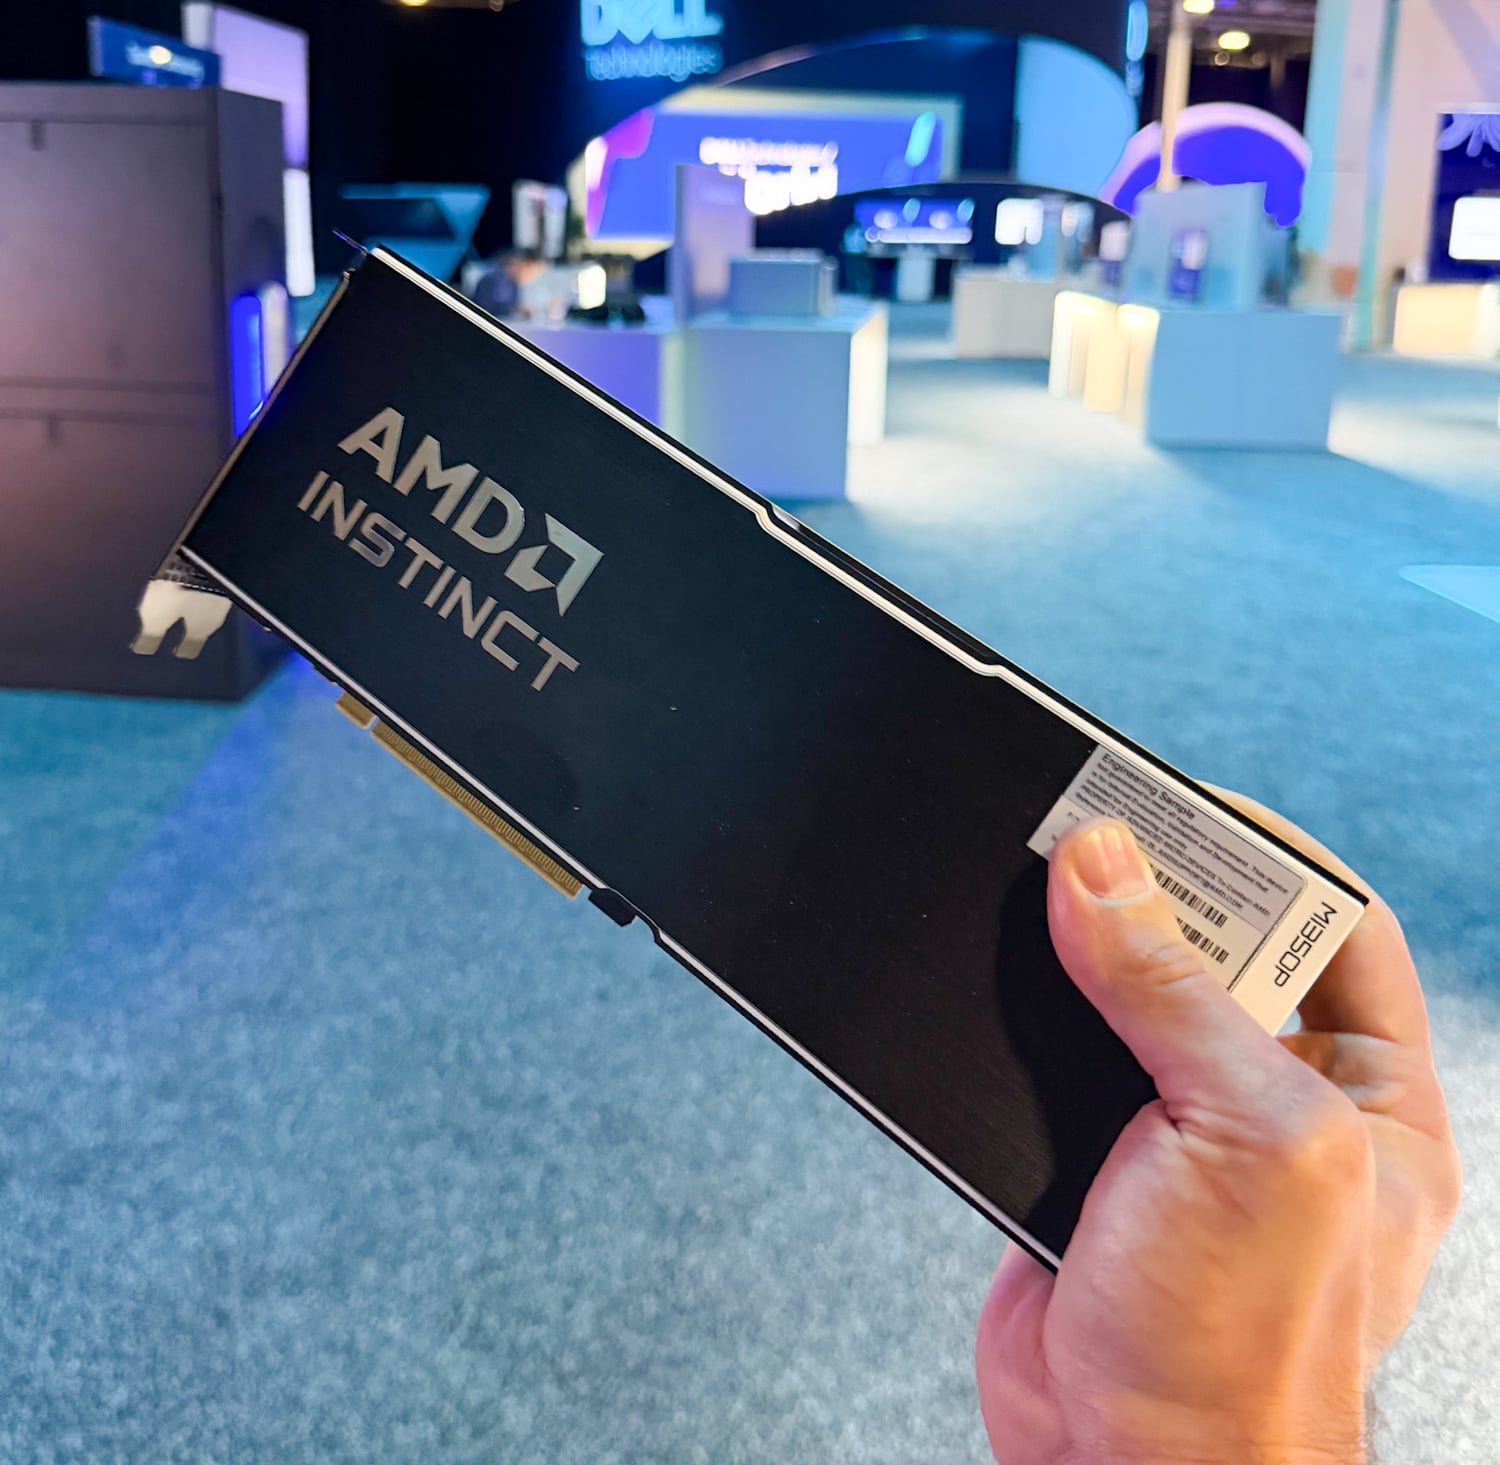
Liqid Pools 30 AMD MI350P GPUs in One Server: 4.3TB of HBM3E and 69 PFLOPS for AI Inference
In late July, Liqid unveiled a scale-up AI platform built around AMD Instinct MI350P PCIe GPUs. The UltraStack 30 pairs Liqid’s composable GPU pooling technology with AMD accelerators to address enterprise and cloud AI inference deployments that need to scale beyond the accelerator count and memory capacity of conventional servers. UltraStack 30: Pooling 30 AMD
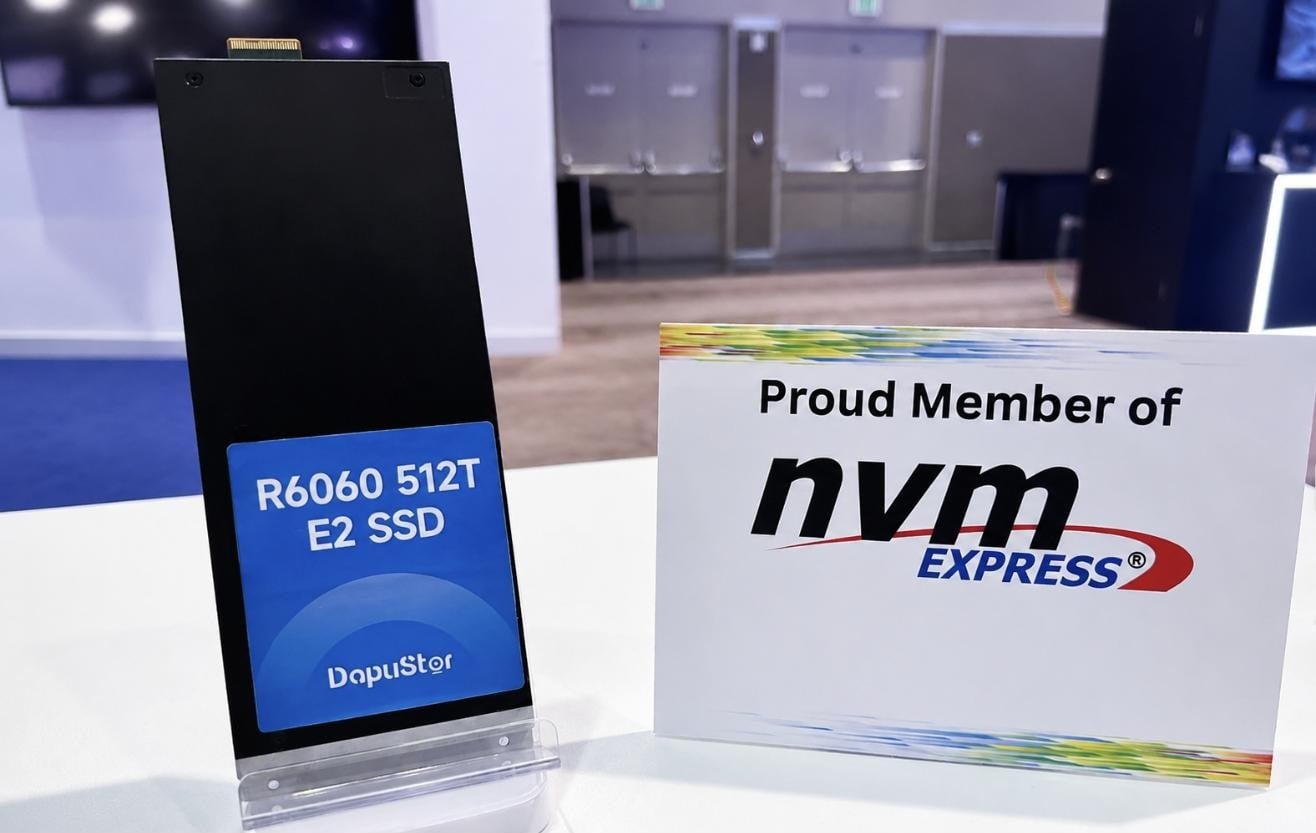
DapuStor Shows a 512TB QLC SSD at FMS 2026: 1PB of Flash in Two Drives
DapuStor used FMS 2026 to show what it calls an industry-first 512TB SSD: a new top capacity for the R6060 PCIe 5.0 QLC line that doubles the company’s previous 245TB design and puts a full petabyte of flash in just two drives. The drive was demonstrated on the show floor through a performance test video,
Volta Comes Out of Stealth With a $10B AI Lab Partnership and a 133MW Vera Rubin Factory in Norway
Volta has emerged from stealth with a vertically integrated AI infrastructure platform designed to combine capital formation, powered land, data center development, GPU compute, software, and operations under one organization. The company is targeting a financing gap in the AI infrastructure market. While the largest technology companies can fund large GPU deployments directly from their
IBM and Together AI Put $240M Into a Dedicated HGX B300 Inference Cluster on IBM Cloud
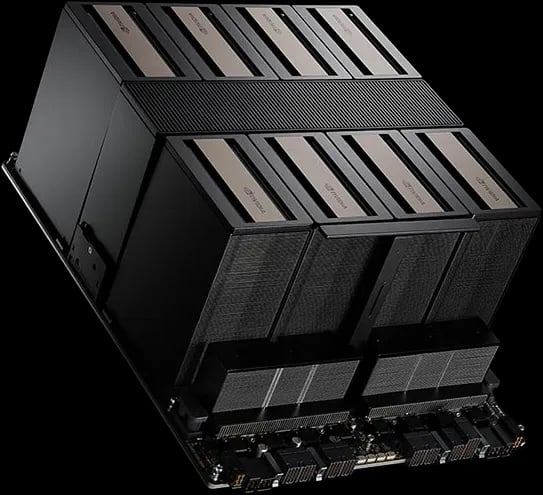
IBM has announced a multi-year, $240 million agreement with Together AI to deploy a dedicated NVIDIA HGX B300-based AI inference cluster on IBM Cloud. Together AI plans to use the environment to deliver inference services for open-source models, expanding its AI Native Cloud platform for enterprise customers. The deployment is positioned as IBM Cloud’s first
Lumilens Exits Stealth With $700M and AI Optics Already Shipping to a Hyperscaler
Lumilens has emerged from stealth with a portfolio of optical interconnect products targeting two networking constraints in large AI clusters: scale-out connectivity between racks and scale-up connectivity among GPUs within a compute domain. The company said it has begun shipping its first scale-out product to production AI data centers for a hyperscale customer under a
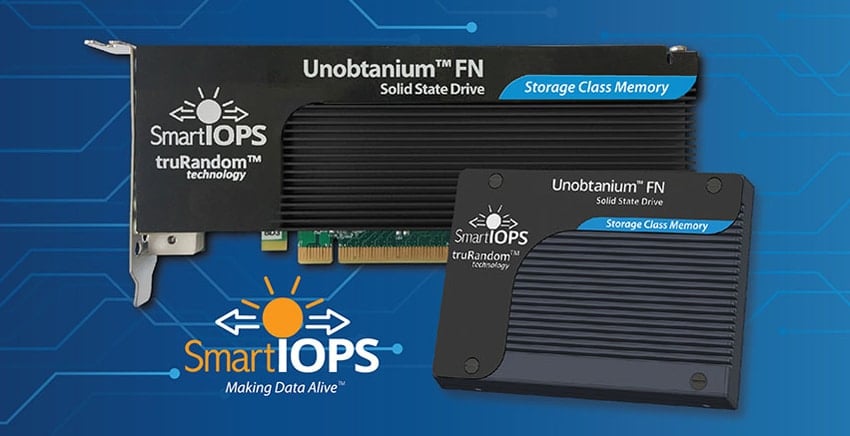
Smart IOPS Unobtanium T50: 50 Million IOPS Per Gen6 SSD, With a One Billion IOPS Appliance Target
Smart IOPS and H3 Platform have announced an AI compute storage platform targeting up to one billion random-read IOPS. The proposed system combines Smart IOPS’ Unobtanium T50 solid-state devices with an air-cooled H3 Platform appliance designed around NVIDIA accelerated computing and networking technologies. The platform targets data-intensive AI inference and analytics workloads that require GPUs
Netlist and Samsung Sign Five-Year Patent, Supply, and Technology Agreements
Netlist and Samsung have signed a five-year set of agreements covering patent cross-licensing, DRAM and NAND supply, technology cooperation, and the settlement of all pending litigation between the companies. “We’re excited to renew this partnership and look forward to working closely with Samsung,” said Netlist CEO C.K. Hong, a nod to the joint development agreement
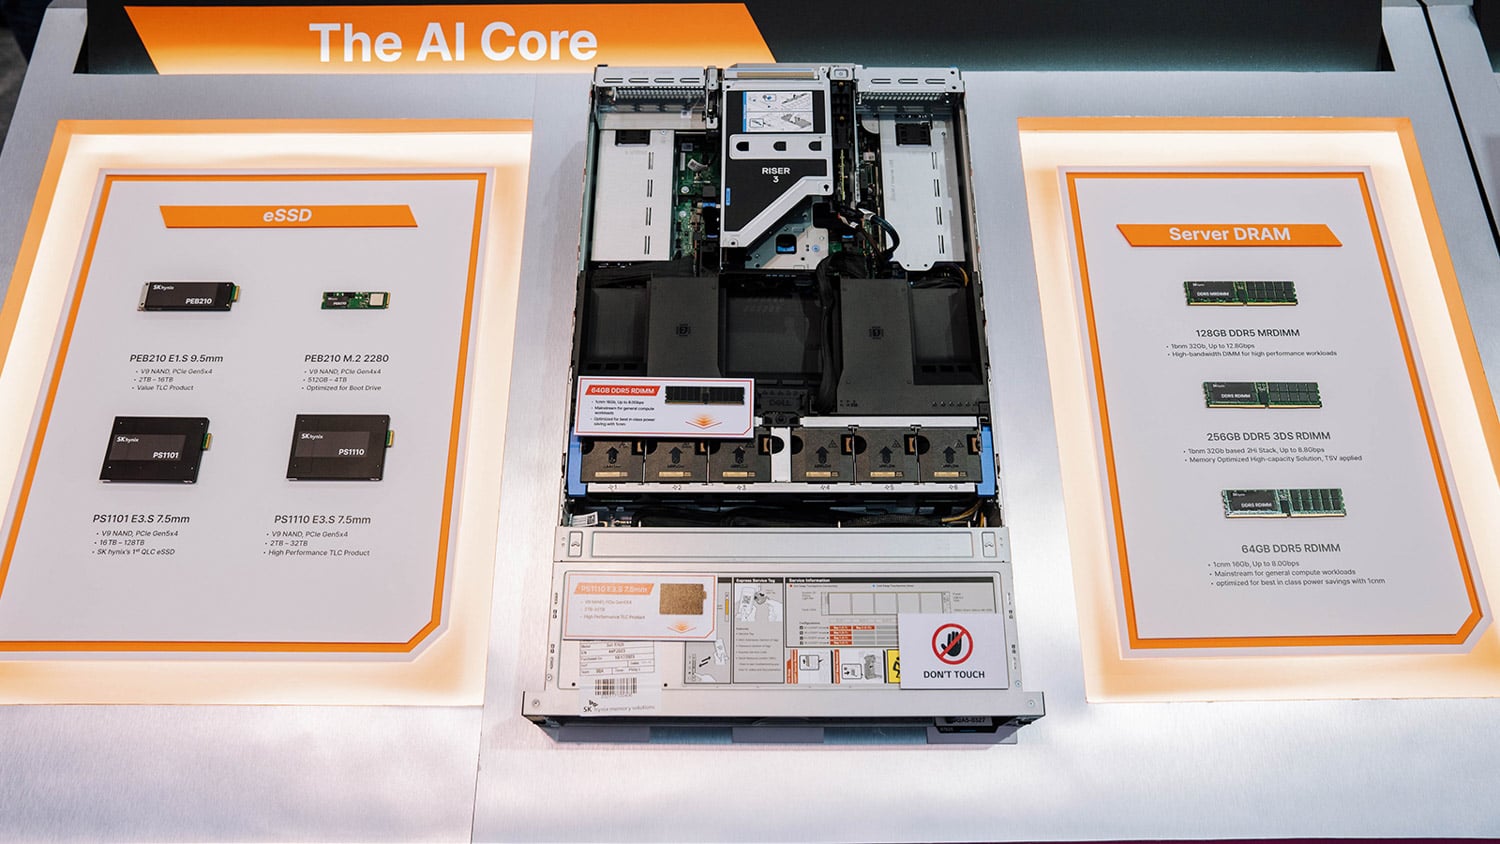
SK hynix at FMS 2026: 16-High HBM4, Wafer-Bonded 375-Layer NAND, and a Tiered Memory Pitch
SK hynix used Future of Memory and Storage 2026, held August 4 to 6 at the Santa Clara Convention Center, to showcase a comprehensive “full-stack” AI memory portfolio spanning HBM, server DRAM, NAND, and CXL expansion. The company’s presence centered on the transition toward agentic AI and the need to shift from individual product performance
AMD to Acquire Taalas, the Toronto Startup Building Silicon Around One Model
AMD has entered into a definitive agreement to acquire Toronto-based Taalas, a developer of specialized AI inference silicon. The acquisition is intended to expand AMD’s inference capabilities as AI deployments shift toward real-time and high-volume production workloads, where efficiency, memory movement, and optimized dataflows are increasingly important. It lands two days after AMD put its


Amazon