

NVIDIA has announced a new GPU for scientific computing at SC26. Rubin HPC is a member of the Vera Rubin platform that puts more than 50,000 CUDA cores on a single GPU, and NVIDIA expects it to be available in 2028. The rest of the company’s SC26 slate covers a 192-CPU Vera rack for simulation work due in early 2027, the Nemotron for Science open model package, new CUDA-X libraries, a quantum codesign platform with IBM and Fermilab, and Lambda’s deployment of co-packaged optics switches.
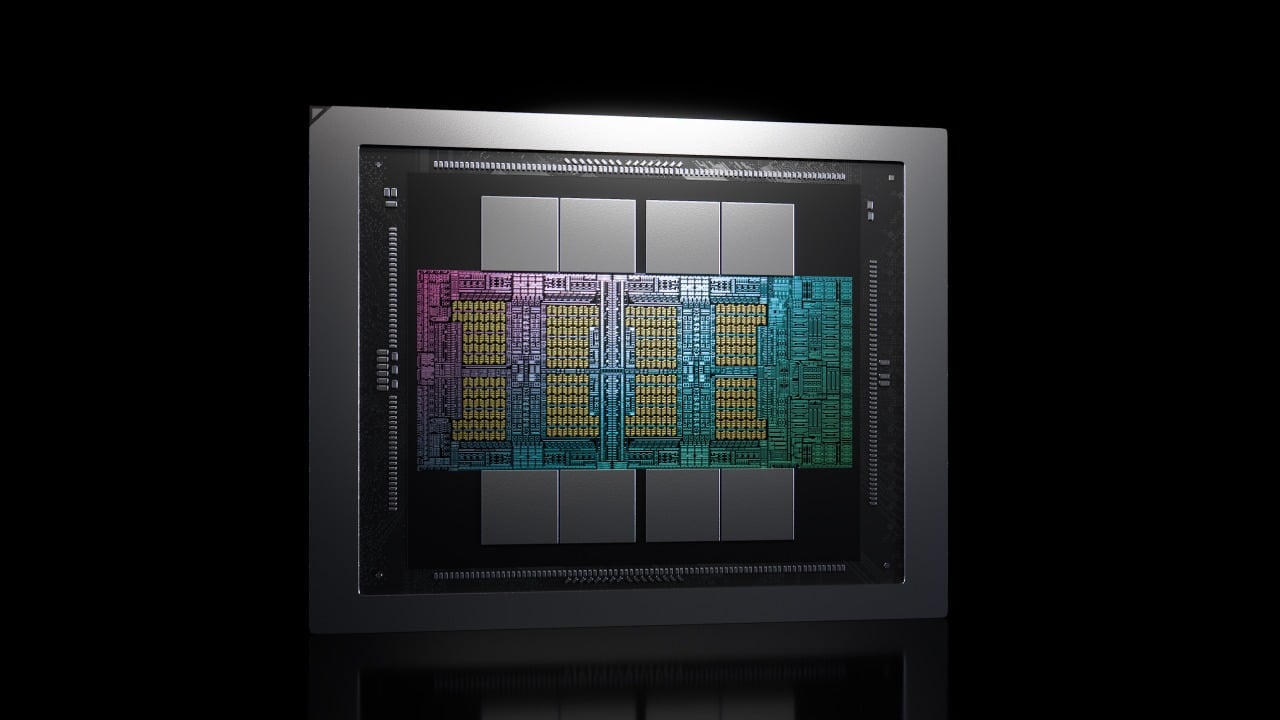
Rubin HPC GPU
NVIDIA describes Rubin HPC as a GPU for simulation and data processing in science, engineering, and analytics, built to scale data movement together with compute. Beyond the core count, which NVIDIA calls a record, the company lists a sparse data acceleration capability that keeps those cores fed with data and GPU-to-GPU links over seventh-generation NVLink. The target workloads are sparse matrix operations, stencil computations, sorting, and reductions, the patterns behind climate models, engineering simulation, genomic analysis, and financial risk.

On stage at SC26, NVIDIA said Rubin HPC triples the performance of simulation and analytics and supports every precision from FP64 to FP4. The company did not name the baseline for the 3x figure, and it has not published memory capacity, FP64 throughput, power, or system configurations. Ian Buck, vice president of hyperscale and high-performance computing at NVIDIA, tied the part to agentic research, saying “faster simulation means faster discovery” for agents working on science and engineering problems. Intel is pitching its FP64-capable GPU D270 at the same simulation workloads at the show.
Vera CPU Racks for HPC
The Vera CPU platform for HPC is a liquid-cooled NVIDIA MGX rack holding 192 Vera CPUs connected by Quantum-X800 InfiniBand, with about 300TB of memory, 1PB of storage, and more than 200TB/s of aggregate peak memory bandwidth. Each 1U tray carries eight CPUs along with NVMe storage and management, and the rack reuses the chassis, power distribution, and cooling of NVL72 systems. Each CPU has 88 Olympus cores, 176 threads, and SOCAMM2 LPDDR5X memory rated at up to 1.2TB/s.

That is a different configuration from the 256-CPU Vera racks Dell and Supermicro announced for agent sandboxes at GTC Berlin, with InfiniBand and SHARP in-network computing added for tightly coupled simulation. NVIDIA says Dell Technologies, HPE, Lenovo, and Supermicro will offer the HPC racks beginning in early 2027. DKRZ, the German Climate Computing Center, has selected Vera CPUs for its Bull-built HLRE-5 supercomputer, which also includes GB200 systems and Quantum-2 InfiniBand and is expected in early 2028.
NVIDIA claims twice the energy efficiency of x86 CPUs for Vera. In its tests, Vera delivered 1.9x the performance and 2.4x the performance per watt of x86 systems on the OpenFOAM motorBike Large case, and it projects 1.6x the performance and 2x the efficiency on the Weather Research and Forecasting model. These are vendor results that we did not run or audit, and NVIDIA did not name the x86 processors. In our Vera CPU review, a two-socket Vera system finished a large OpenFOAM mesh 1.44x faster than a 384-core EPYC 9965 system and 1.20x faster than a 240-core Xeon 6978P system.
On software, NVIDIA HPC SDK 26.11 is available now with compilers and libraries tuned for Vera, and a next-generation Fortran compiler built with HPC centers and national labs is in public beta. NVIDIA says the compiler runs existing Fortran programs faster on its platforms with no code rewrite.
Nemotron for Science and CUDA-X Libraries
Nemotron for Science packages the Nemotron 3.5 Super VL open model with scientific evaluations, post-training recipes, and LitmusBench v0.2, an open dataset of nearly 50,000 chemistry reasoning questions. The model and dataset are available now on Hugging Face, and NVIDIA says the model has been optimized to run locally on a 128GB DGX Spark. Argonne National Laboratory is integrating it into its StructBioReasoner multi-agent system for protein-based therapeutics, and RIKEN has made it available on its RIKYU AI supercomputing platform.
Among customers that post-trained the model, Lila Sciences nearly doubled quantum-dot synthesis accuracy to 61%, which NVIDIA says tops GPT-6 Astra’s 54% at 10x to 20x lower inference cost. Terray Therapeutics recovered about 76% of annotated reactions on the RxnScribe test for reading chemical reaction diagrams. A KTH Royal Institute of Technology agent repaired 81% of broken GROMACS molecular dynamics setups in one overnight run on a single DGX Spark.
Among the CUDA-X additions, the cuPhoton toolkit correlates Event Horizon Telescope observations in eight minutes, where the analysis previously took more than a month. cuPotential speeds existing molecular simulation software by up to 3x, and Daviator, a set of batched GPU kernels for the Vienna Ab initio Simulation Package, runs quantum-mechanical calculations up to 22x faster at up to 75% lower cost. NVIDIA did not state the baselines for the cuPotential and Daviator figures.
cuSpa and a GPU-accelerated HMMER library are now open source. cuSpa delivered a 900x speedup over CPUs on cell polygon calculations at Memorial Sloan Kettering Cancer Center, and the HMMER library ran benchmark searches up to 84x faster than standard HMMER at Basecamp Research. The rapids-singlecell library, co-developed with scverse, now ships in a single container built for agents, and 10x Genomics has integrated it into its Sentira platform.
Quantum Codesign With IBM and Fermilab
On quantum, NVIDIA and IBM are colocating NVIDIA DGX B200 systems with IBM quantum computers, including systems running the IBM Quantum Nighthawk processor, to support a modular quantum codesign platform developed with Fermilab. Researchers will use it to evaluate error-correction codes, decoding algorithms, and quantum-classical applications for high-energy and nuclear physics. IBM set up a similar arrangement with AMD and Oak Ridge National Laboratory, pairing Nighthawk with an Instinct MI355X cluster. NVIDIA gave no system counts, location, or timeline.
Separately, NVIDIA released TCBP-JOBS, a decoding algorithm in the CUDA-Q QEC 0.9.0 library that it says decodes up to 13,000x faster than leading existing algorithms and cuts the computation behind new quantum computer designs from 12 weeks to 45 minutes. The CUDA-Q platform also gains a decoder server, an expanded set of fault-tolerant primitives, a CUDA-Q Algorithms library of reusable application components, and CUDA-Q Pulse for shaping the control pulses that drive qubits.
NVIDIA says quantum processor deployments at supercomputing centers have grown nearly sevenfold in five years, with nearly 30 centers now deploying more than 50 processors. Slurm 26.11, due later in November, adds a quantum interface that lets a QPU builder describe its hardware once, in a single file, and reuse that integration at every center. It supports the QRMI and QDMI quantum-HPC interfaces, with IBM contributing through its Quantum Resource Management Interface, so centers can schedule quantum processors alongside CPUs and GPUs. Alice & Bob, IBM, IQM, Pasqal, Quantinuum, and MQSC are adopting it, and NVIDIA acquired Slurm developer SchedMD in late 2025.
NVIDIA also pointed to quantum-classical chemistry work by IBM and RIKEN, a finalist for the 2026 ACM Gordon Bell Prize, which calculated binding energies for protein-ligand complexes of up to 12,635 atoms. That is more than 40x the previous 303-atom quantum-classical benchmark. The classical side ran on RIKEN’s ROQUO supercomputer, which is built on NVIDIA GB200 systems and Quantum-X800 InfiniBand.
Among ecosystem projects on the platform, Altera and Oxford Quantum Circuits built an FPGA-based quantum controller that connects qubit control and readout to GPUs through NVQLink, and Quantum Motion integrated its QUICHE chemistry framework with CUDA-Q. QunaSys used cuQuantum and 1,024 NVIDIA Hopper-generation GPUs on ABCI-Q to simulate more than 300 million quantum operations, reaching chemical accuracy for a four-hydrogen-atom model. NVIDIA researchers used the JUPITER supercomputer to simulate 104 qubits under realistic noise.
Lambda Deploys Co-Packaged Optics
Lambda is using NVIDIA Photonics co-packaged optics (CPO) switches to connect GB300 NVL72 racks in a deployment of more than 10,000 GPUs. Each switch has 144 ports at 800Gb/s and 18 external light sources that technicians can replace in the field, where a failed laser in a pluggable optic means swapping the whole module. Testing cited by NVIDIA showed network latency about 4% lower at rack scale and up to about 10% lower at pod scale, with the same throughput as pluggable optics.

Median optics temperature in the deployment was 36°C, against 51°C for conventional pluggable optics. NVIDIA rates its photonics switches at up to 5x better power efficiency, up to 15x higher reliability, and 4x fewer lasers than pluggable designs. NVIDIA also used the show to mark 20 years of CUDA, which it says now has more than 11 million developers and more than 1,000 CUDA-X libraries.


 Amazon